
Ollama v0.40.4-rc0 Updates llama.cpp for Decision Models, Reuses Manifests, Lists Models in Codex Picker
Ollama v0.40.4-rc0 is a pre-release that updates llama.cpp to b11521 for decision models and EmbeddingGemma 2, reuses manifests in inference routes, compacts MLX state, and surfaces local models in the Codex picker. Here is how to test it.
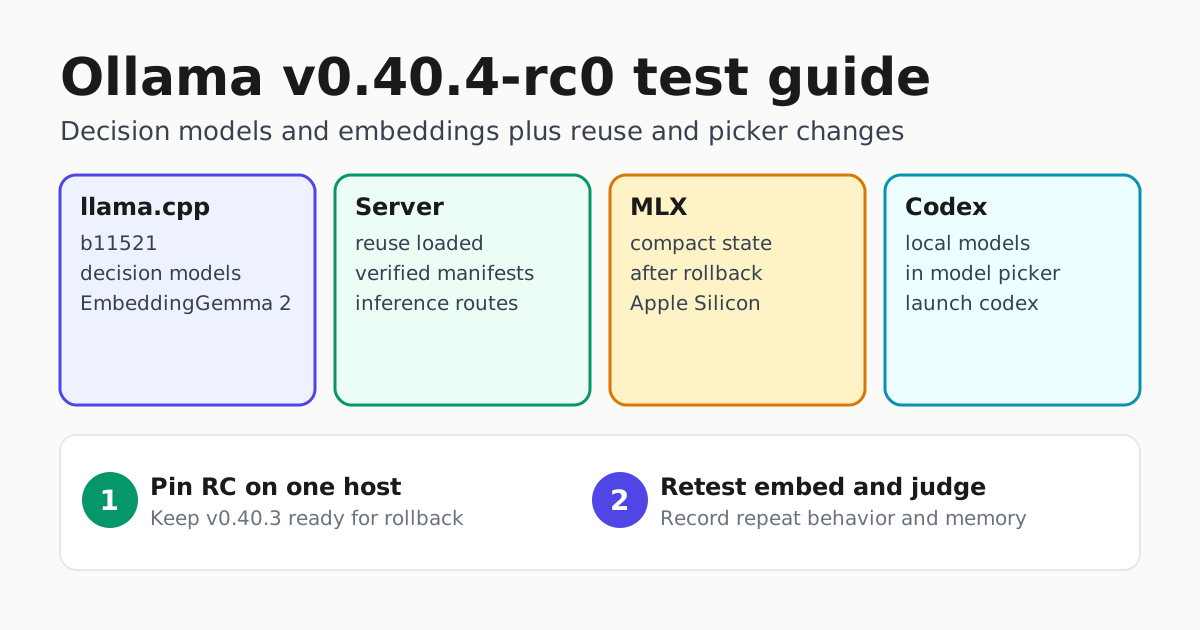
Ollama has put its next patch into public testing. The v0.40.4-rc0 release notes list five changes on top of v0.40.3, with implications for anyone running local models behind coding agents, embeddings, or decision-model routing.
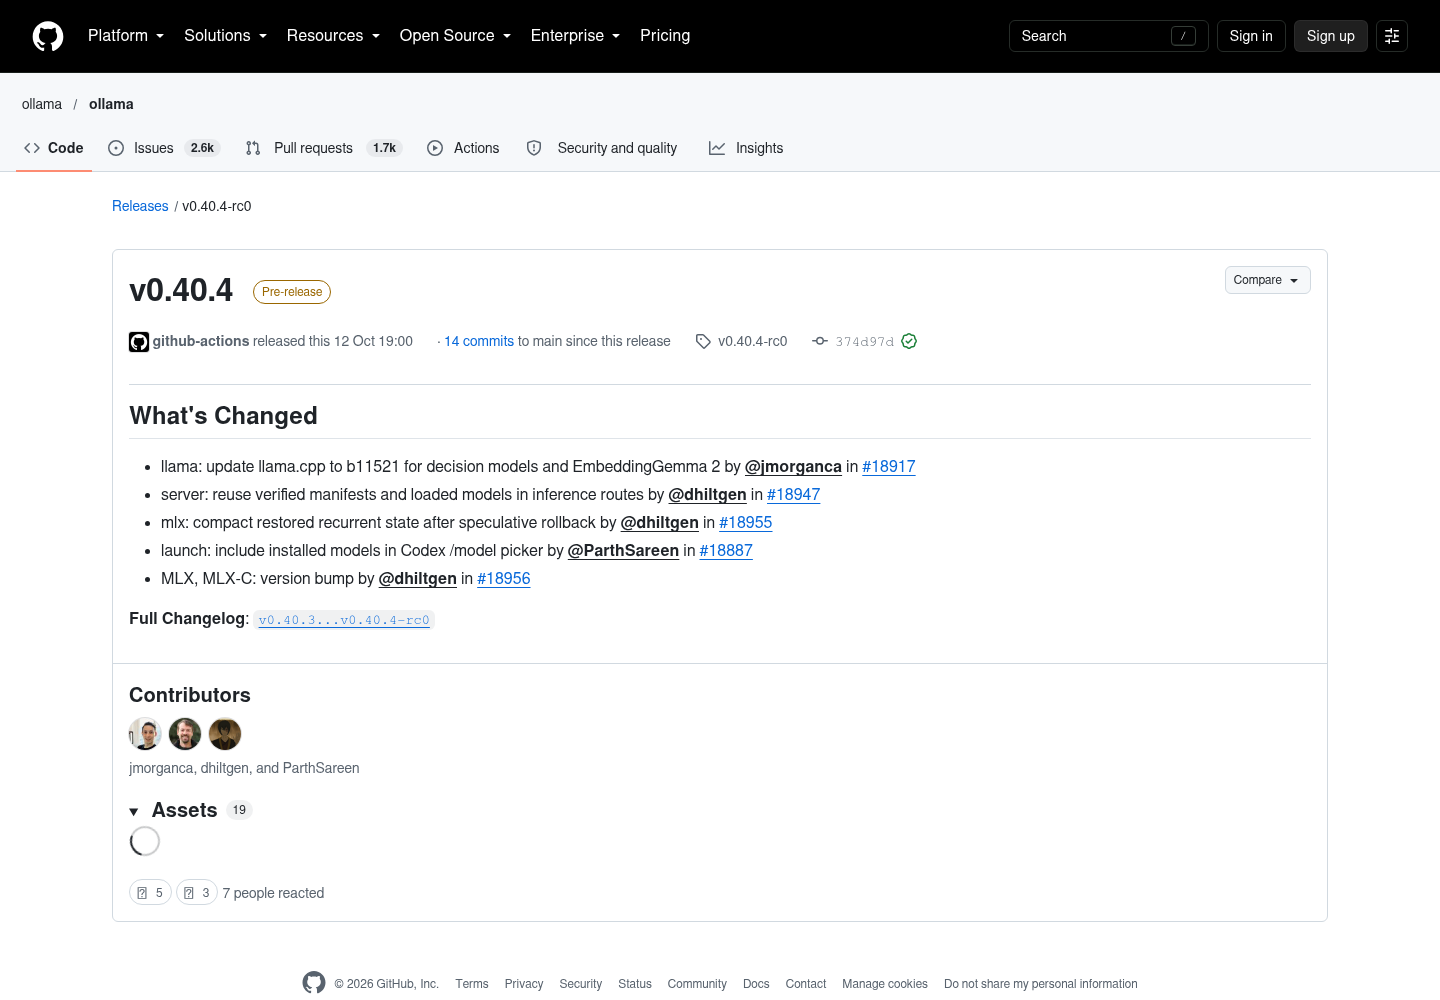
This is a pre-release, not the stable update. The releases index showing v0.40.4 pre-release alongside v0.40.3 latest still shows v0.40.3 as Latest, while v0.40.4-rc0 is marked Pre-release. If you pin Ollama for a fleet, keep production on stable and test this RC on one machine first.
What changed in v0.40.4-rc0
The RC lists five pull requests from three contributors:
| Change | Listed scope | What to check |
|---|---|---|
| llama: update llama.cpp to b11521 for decision models and EmbeddingGemma 2 | Runner update named for decision models and EmbeddingGemma 2 | Retest your decision and embedding prompts and compare answers to stable |
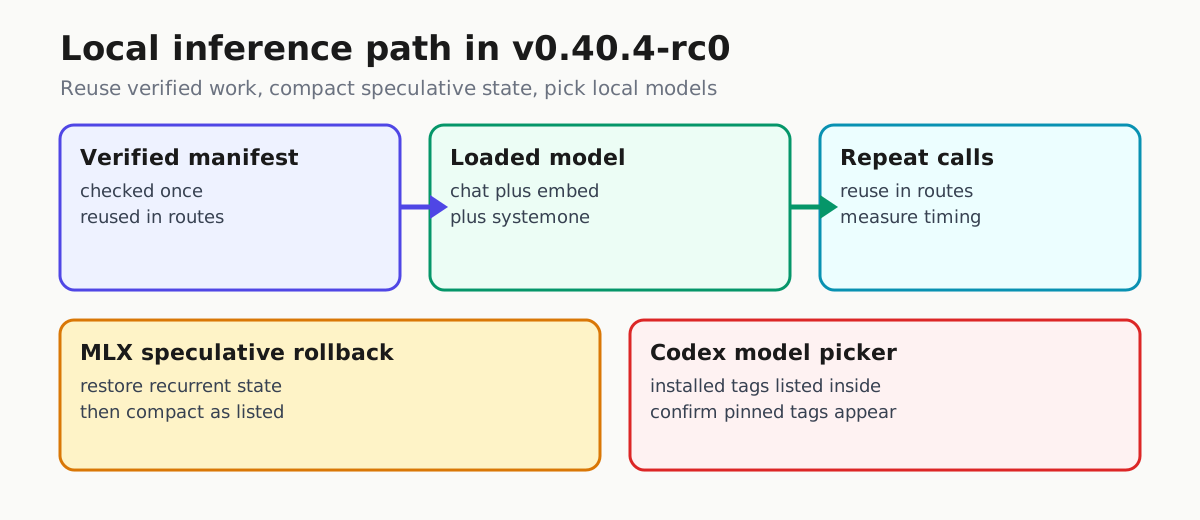
| server: reuse verified manifests and loaded models in inference routes | Reuse of already-verified manifests and already-loaded models across inference routes | Measure repeat-call timing and loaded-model behavior on your workload |
| mlx: compact restored recurrent state after speculative rollback | Compaction step after restored recurrent state on speculative rollback | Observe long Apple Silicon runs and record memory and completion behavior |
| launch: include installed models in Codex /model picker | Installed Ollama models listed inside the Codex /model picker |
Confirm your pinned tags appear and selection routes as expected |
| MLX, MLX-C: version bump | Version bump for the MLX runtimes | Rerun your Apple Silicon golden prompts and note any behavior change |
The ollama/ollama repository is the primary source for the code behind all five changes. The full diff for operators is v0.40.3...v0.40.4-rc0.
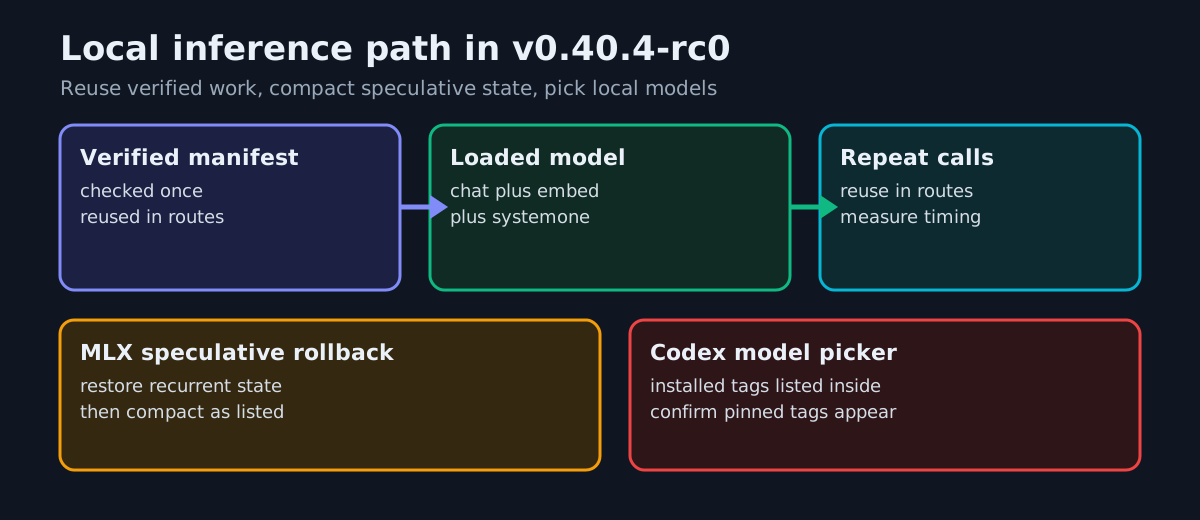
Decision models and embeddings: what to retest
Ollama added decision models through /v1/systemone in v0.35, starting with Nimble and Tev1 for choice, noul, and score questions, then added Clef and Clef Flash as multimodal decision models. This RC names decision models and EmbeddingGemma 2 in its llama.cpp update entry.
If you already use decision gates, retest the same prompts you use in production. Our related coverage of Ollama 0.40.2 background upgrades and kept backups explains why upgraded local models can temporarily use extra disk. Keep that cleanup in mind before pulling large embedding or decision weights for this RC.
For embeddings context, see EmbeddingGemma 2 open multimodal on-device embeddings for background, then measure recall and throughput locally rather than assuming parity with your current embedder.
Practical checks for this RC:
- Pull once, then run back-to-back inference to exercise the listed manifest and model reuse path.
- Run an embedding batch and a decision-model batch separately to isolate regressions.
- On Apple Silicon, run a long MLX generation and record memory and output behavior at fixed intervals.
# Post-install checks - RC already installed on test host only
ollama --version # confirm v0.40.4-rc0 before testing
ollama pull embeddinggemma-2
ollama pull nimble # required before the decision-model example below
ollama list
# Decision-model smoke test via supported decision endpoint
# Requires nimble already installed via ollama pull nimble above
curl http://localhost:11434/v1/systemone \
  -H "Content-Type: application/json" \
  -d '{
    "model": "nimble",
    "state": "Checkout has returned 500 errors since 9am.",
    "questions": {
      "label": {
        "type": "choice",
        "instructions": "Which label fits this ticket?",
        "criteria": {
          "billing": "Payments and refunds",
          "bug": "Software errors",
          "account": "Login and account access"
        }
      }
    }
  }'
For embeddings, re-run your existing embedding workflow with embeddinggemma-2 installed and compare recall and throughput locally rather than assuming parity with your current embedder.
If you route cheap models before escalating, keep your thresholds unchanged for the first run. See Use Jev to Route Cheap Models Without Guessing for a pattern that pairs well with local decision models: use the small local judge for triage, log confidence, and escalate only on low confidence.
Server reuse and MLX compaction
The server entry is listed as reuse of verified manifests and loaded models in inference routes. Treat any timing or reliability effect as a hypothesis to measure on your setup when an agent calls /api/chat and /v1/systemone in a loop.
What to measure:
- Time to second request with the same model loaded versus cold start
- Error rate on your library size and route mix
- Disk use if you previously kept ggml backups after the 0.40 upgrade path
For history: the v0.34.4 notes document a fix for intermittent model-not-found errors with a large local library, while the v0.40.2 notes document a fix for duplicate list entries for upgraded models plus background upgrade handling. They are separate issues.
On MLX, the listed change is compaction of restored recurrent state after speculative rollback. That entry concerns Apple Silicon hosts where supported architectures run on MLX by default since v0.40.0. If you test it, use this bounded plan:
- Use one Apple Silicon test host with runtime assignment unchanged between stable and RC
- Run the same long generation prompt on v0.40.3, then on v0.40.4-rc0
- Record the runner used from server logs, note any speculative rollback messages, and sample memory use in Activity Monitor at fixed intervals
- Do not change Metal settings or swap runtimes during the comparison
Do not infer lower memory use or faster repeat calls from the release titles alone. Log the numbers and compare.
Codex picker now lists installed models
The ollama launch codex integration lists installed models in the Codex /model picker according to the release notes.
The release notes list installed Ollama models inside the Codex /model picker. You can verify inside Codex that your pinned tags appear and selection routes as expected.
ollama list
ollama launch codex
# Inside Codex, open /model and confirm
# your pinned tags appear
Test this with two or three of your pinned chat tags. For decision-capable models, check ollama show capability output and use the /v1/systemone decision endpoint as documented in the v0.35.x history, which reports decision-only capability so clients do not offer those models for general chat, tools, or thinking. Confirm picker behavior against that capability output on your build before changing any routing.
Should you deploy it?
No, not yet to production. This is a release candidate published Oct. 12 at 19:00 UTC as commit 374d97d, with 14 commits to main since that tag at capture time. The stable line remains v0.40.3 from Oct. 11.
Use this RC to:
- Validate EmbeddingGemma 2 behavior on your hardware
- Validate decision-model answers have not shifted on your golden tickets
- Confirm Codex picker lists your pinned tags
- Record MLX behavior on long runs for later comparison
Pin the RC version in test, save ollama show output for each model, and keep v0.40.3 images ready for rollback. If all four checks pass, you will be ready when v0.40.4 goes stable without rushing a fleet-wide upgrade on release day.