We use cookies to measure how the site is used and how our ads perform (Google Analytics and Ads, Microsoft Clarity, and the Meta, OpenAI and X ad pixels). “Essentials only” turns off advertising cookies everywhere, and analytics too in the EEA, UK and Switzerland. Privacy Policy
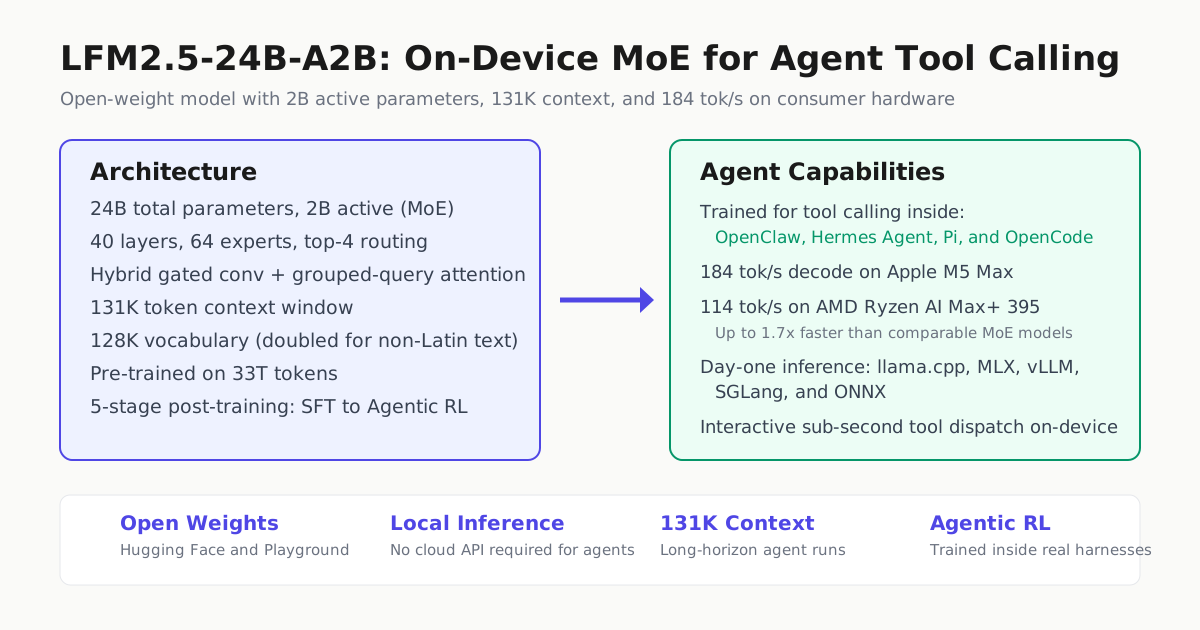
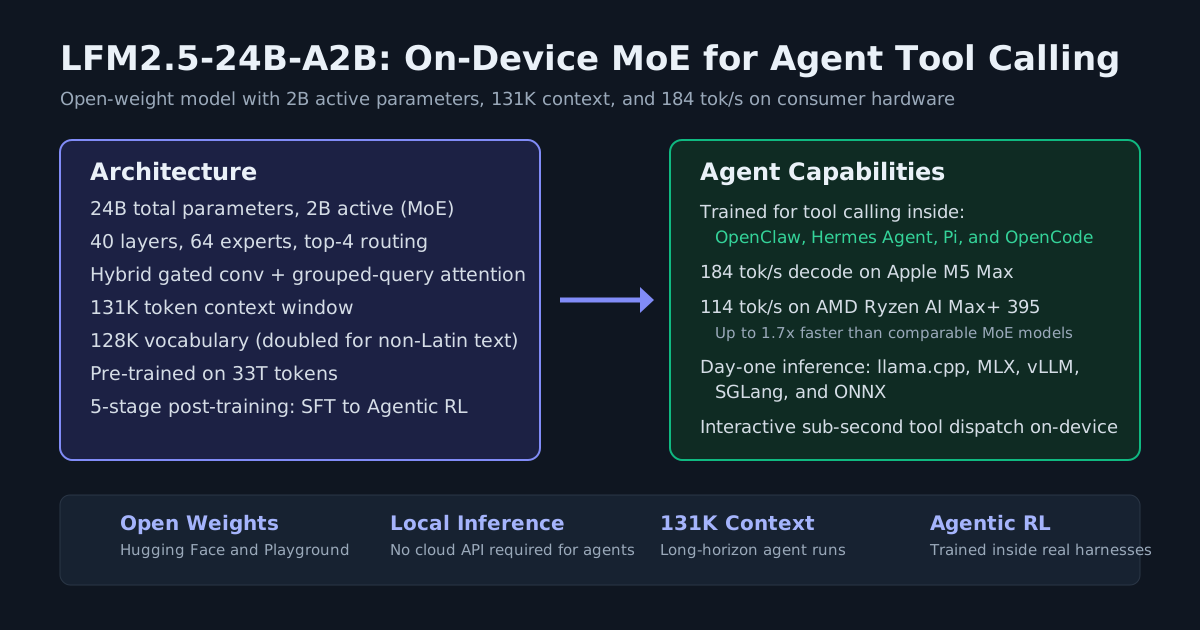
Liquid AI releases the final LFM2.5 model with open weights, 131K context, and tool-calling post-training. It decodes 184 tok/s on an Apple M5 Max and leads AutomationBench by 3× over the next-best MoE.
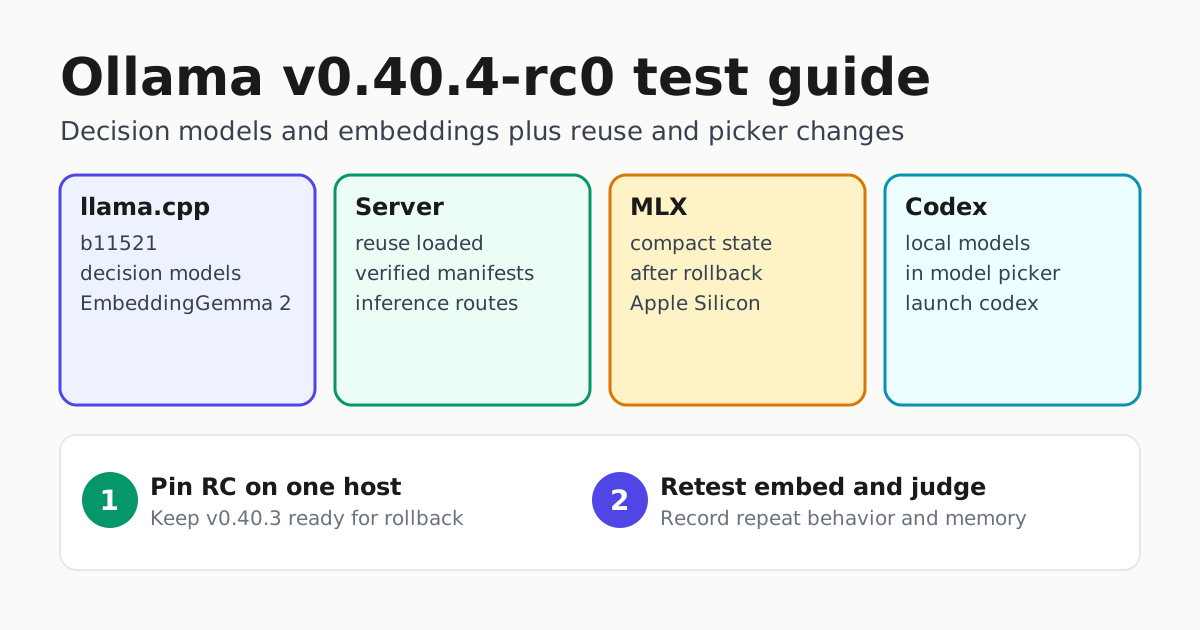
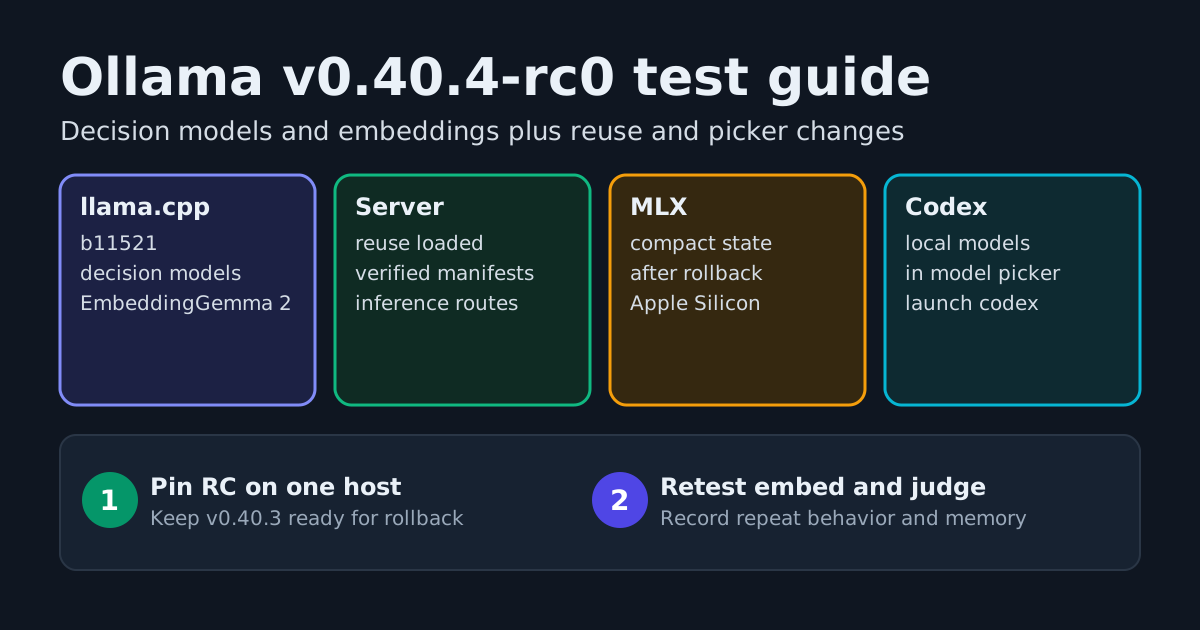
Ollama v0.40.4-rc0 is a pre-release that updates llama.cpp to b11521 for decision models and EmbeddingGemma 2, reuses manifests in inference routes, compacts MLX state, and surfaces local models in the Codex picker. Here is how to test it.
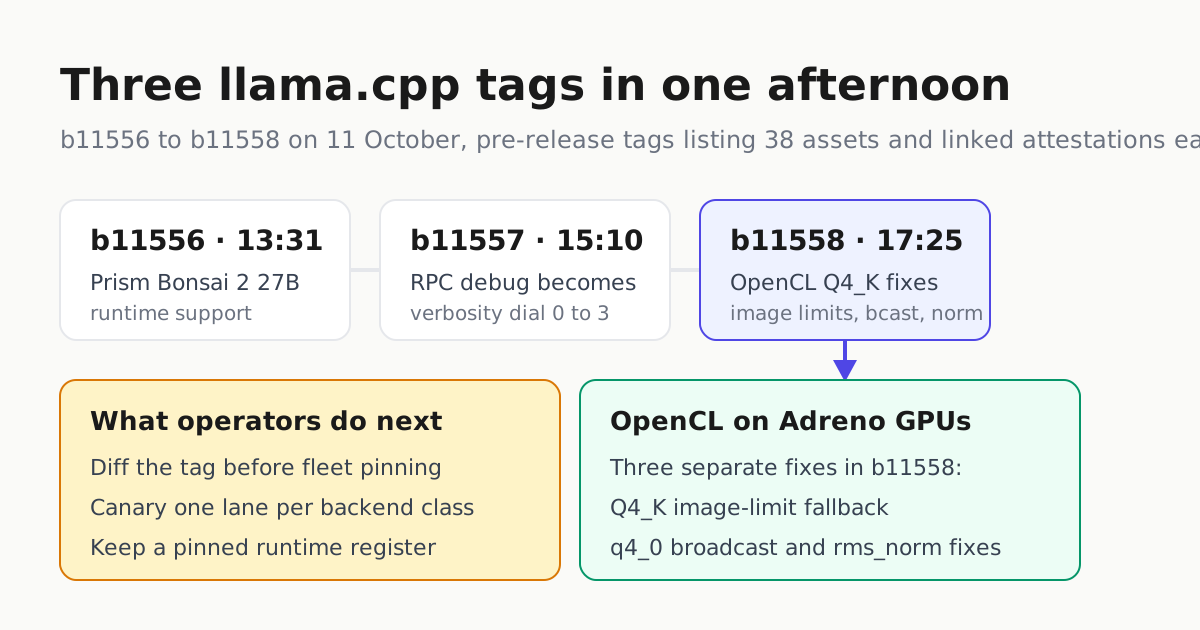
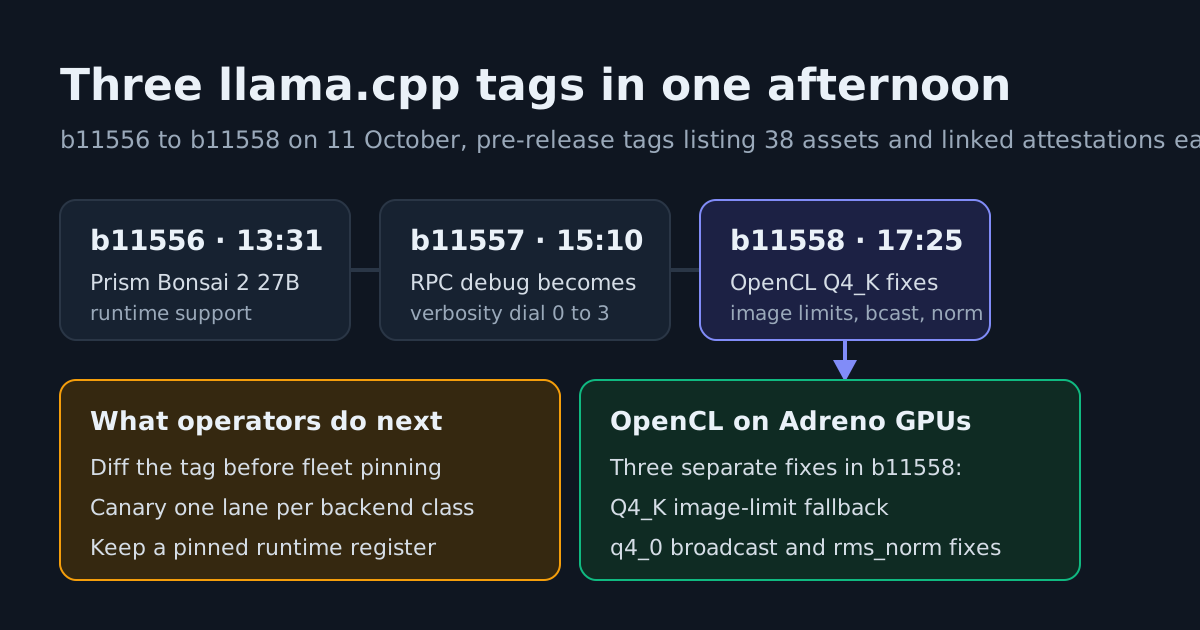
llama.cpp pushed three pre-release binary tags in under four hours on 11 October. The newest, b11558, fixes OpenCL image-limit handling for Q4_K dense bin kernels plus q4_0 broadcast and rms_norm subgroup issues. Here is what changed and how to roll it out safely.