Anthropic Degraded claude.ai, the Claude API and Claude Code on Nov 13: Two Outages in One Morning, Connectors Still Down
Anthropic's status page records two Nov 13, 2026 incidents: sign-in failed until 11:58 UTC, then elevated errors, with connectors still degraded at 14:36.
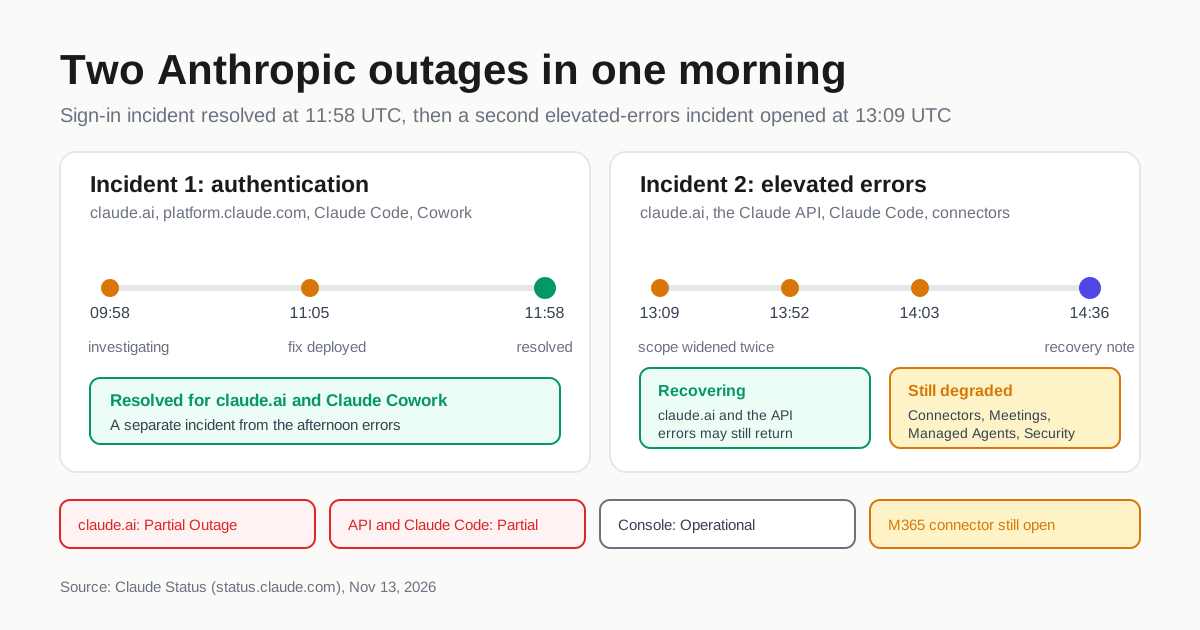
Anthropic’s own status page records two separate incidents on Nov 13, 2026. The first was an authentication failure, resolved at 11:58 UTC. The second opened at 13:09 UTC as degraded performance across claude.ai, the Claude API and Claude Code, and was still open at 14:36 UTC, when the publisher saw recovery on the first two surfaces only. For anyone running Claude Code sessions, API-backed agents or unattended CI jobs, that is two interruptions to core surfaces in one morning.
What the status page says
The Nov. 13 elevated-errors incident is the one to read carefully, because its scope grew twice and then split.
| UTC | Incident | Reported state |
|---|---|---|
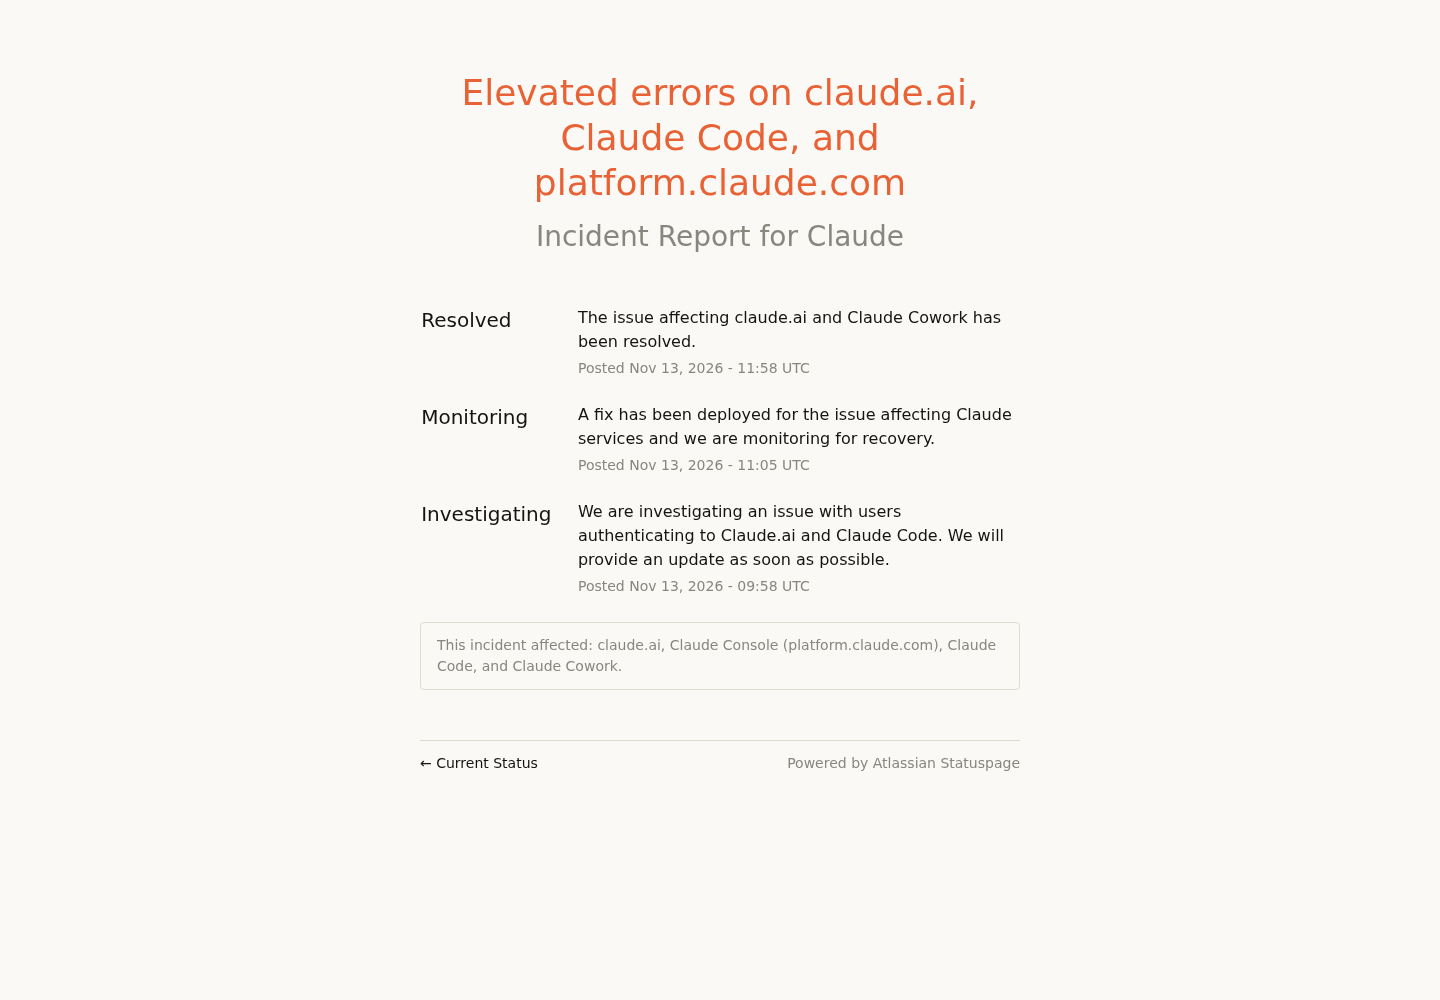
| 09:58 | Authentication | Sign-in issues under investigation |
| 11:05 | Authentication | Fix deployed, monitoring for recovery |
| 11:58 | Authentication | Resolved for claude.ai and Claude Cowork |
| 13:09 | Elevated errors | Degraded performance on claude.ai, the Claude API and Claude Code |
| 13:52 | Elevated errors | Scope widened to connectors, including Claude Docs and Sheets |
| 14:03 | Elevated errors | Scope widened to Claude Security and Claude Managed Agents |
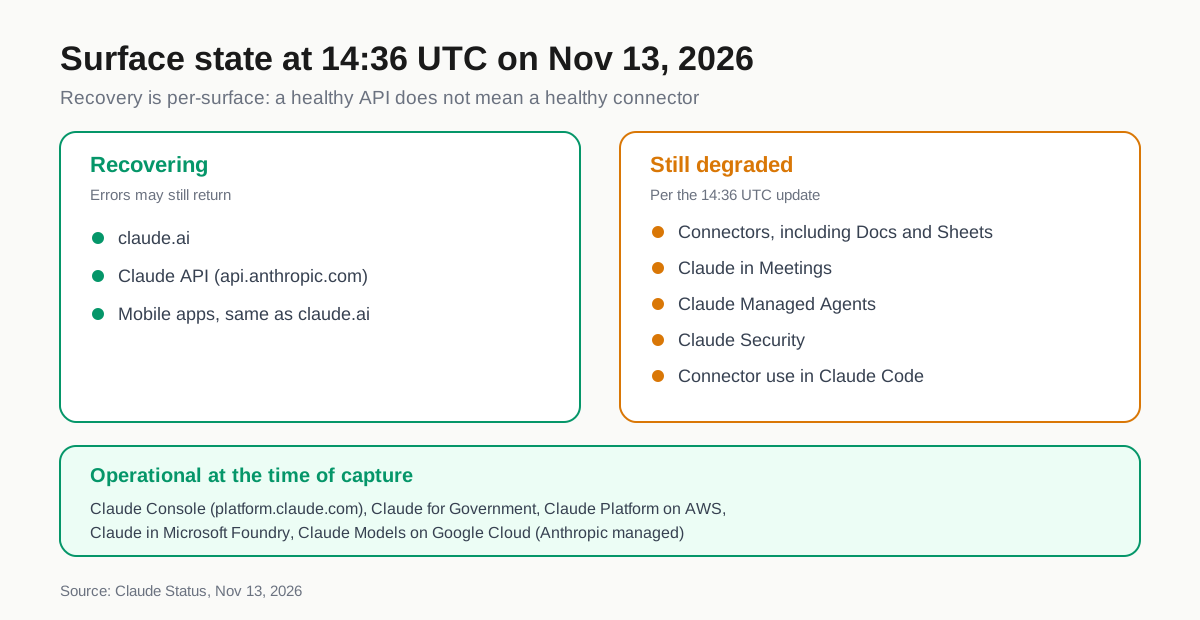
| 14:36 | Elevated errors | Core surfaces recovering; connectors, Meetings, Managed Agents and Security still degraded |
The 09:58 to 11:58 block belongs to a separate authentication incident, whose affected components were claude.ai, Claude Console (platform.claude.com), Claude Code and Claude Cowork.
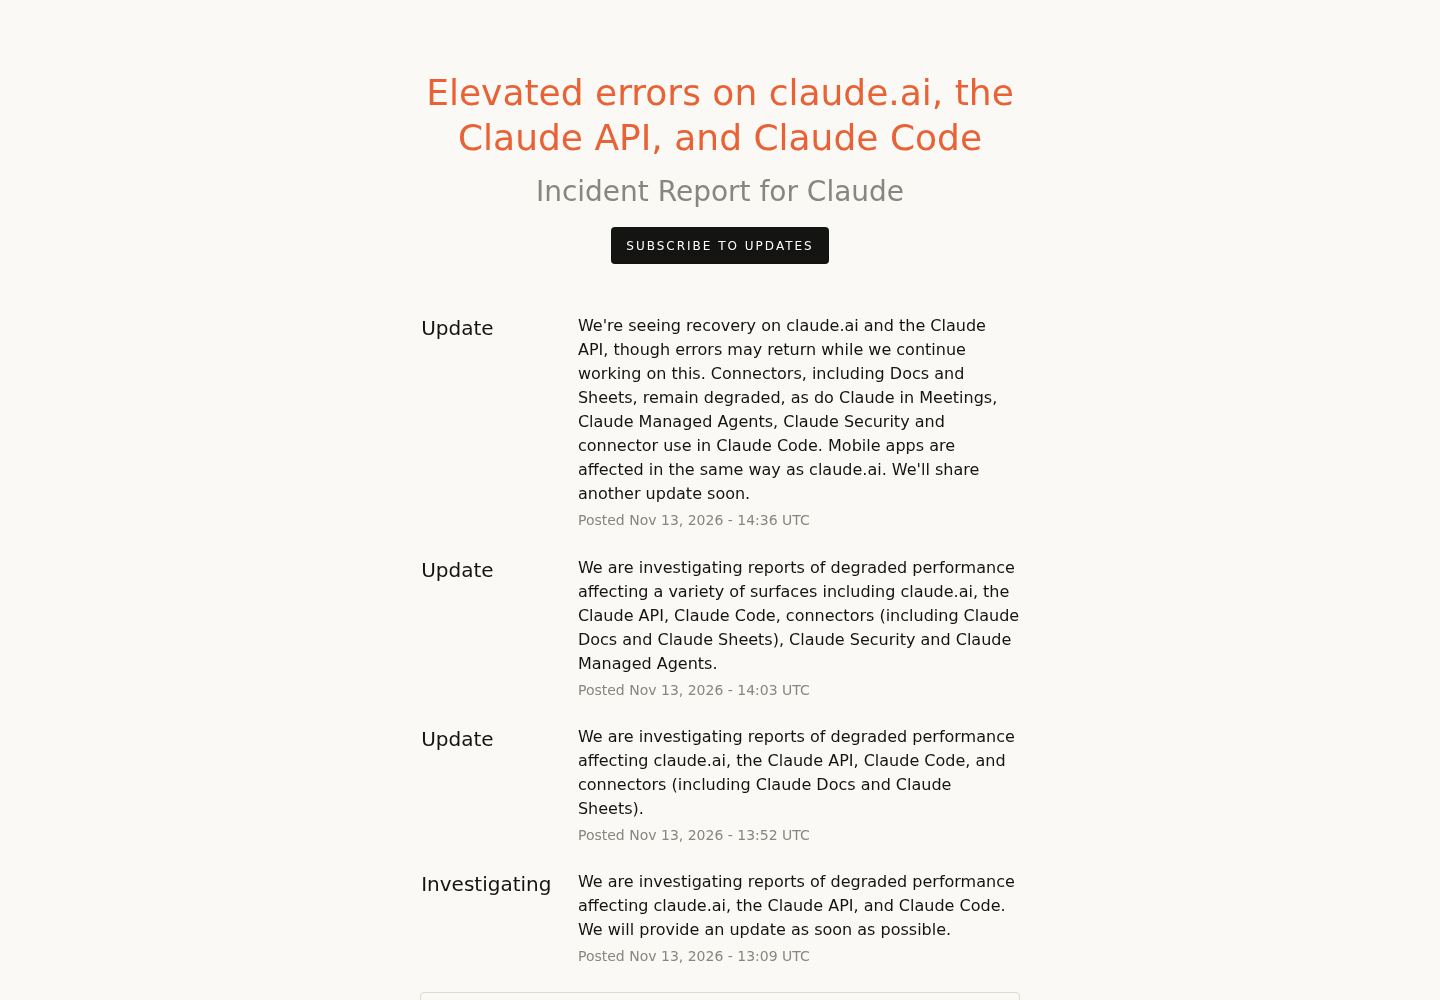
At 14:36 UTC Anthropic wrote that it was seeing recovery on claude.ai and the Claude API, “though errors may return while we continue working on this”, and that connectors including Docs and Sheets remained degraded, as did Claude in Meetings, Claude Managed Agents, Claude Security and connector use in Claude Code. Mobile apps were affected like claude.ai.
The component board at capture time
The Claude Status page listed claude.ai, the Claude API (api.anthropic.com) and Claude Code as Partial Outage, and Claude Cowork as Degraded Performance. Claude Console, Claude for Government, Claude Platform on AWS, Claude in Microsoft Foundry and Claude Models on Google Cloud were Operational.
A third failure with a different owner
The Microsoft 365 connector incident Anthropic opened on Nov. 12 was still unresolved, and its owner was not Anthropic. Anthropic attributed it to a Microsoft 365 service incident: mail, calendar and search tools were failing for most requests, Claude for Outlook remained affected, and Anthropic pointed readers at Microsoft’s status page.
A fault Anthropic is waiting on does not clear because you retried harder. Watch Microsoft’s service health instead of rewriting your retry policy.
Not an isolated morning
The same status page shows elevated errors on Fable 5.2 and Mythos 5.2 on Nov. 10, mitigated after four minutes, and a Claude Fable 5.1 degradation on Nov. 8. Three incidents on the same core surfaces in six days make bounded idempotent retries and a per-surface status gate a design requirement.
What to do about it
- Treat recovery as per-surface. The 14:36 note says the API is recovering “though errors may return”, while connectors are still degraded. Gate each lane on the surface it uses.
- Make retries idempotent and bounded. Use exponential backoff with jitter, cap the attempt count, and make the operation safe to repeat.
- Wait for the state you need, not for a page update. A recovery note is not a resolution.
- Separate connector work from core work in CI, so steps needing Docs, Sheets or Meetings fail into a retry queue, not a run that only needed the API.
- Log the failure class. An overload event, an authentication failure and elevated errors need different responses: backoff, re-authentication, or waiting.
- Keep a fallback path for unattended lanes and rehearse it. See Rehearse the Provider Cutoff: Model Failover for Agent Fleets and Managed Agents Comparison: Bedrock, Claude, OpenAI. Pick Failover First.
- Give operators a status signal, not a status page. A per-surface dashboard, readable before a long job starts, is the difference between a retry loop and a wasted night of compute: OSC 7501: The Agent Status Protocol Your Fleet Dashboard Should Consume.
Bounded retries with a stable idempotency key are the shape of code that survives this kind of morning. This example reads the key and the model from the environment, so it runs as written once ANTHROPIC_API_KEY and ANTHROPIC_MODEL are exported:
import os
import random
import time

import requests

API = "https://api.anthropic.com/v1/messages"
API_KEY = os.environ["ANTHROPIC_API_KEY"]
MODEL = os.environ["ANTHROPIC_MODEL"]


def call_with_bounded_retries(prompt, idempotency_key, max_attempts=6):
    for attempt in range(max_attempts):
        response = requests.post(
            API,
            headers={
                "x-api-key": API_KEY,
                "anthropic-version": "2023-06-01",
                "idempotency-key": idempotency_key,
            },
            json={"model": MODEL, "max_tokens": 1024,
                  "messages": [{"role": "user", "content": prompt}]},
            timeout=120,
        )
        if response.status_code < 500:
            return response
        time.sleep(min(60, 2 ** attempt) + random.uniform(0, 1))
    raise RuntimeError("surface still degraded, do not relaunch until status is Operational")
The last line is the point: once the attempt budget is spent the run stops instead of burning quota against a degraded connector.
What to watch next
Anthropic said it would share another update. The open questions are whether connectors, Claude in Meetings, Claude Managed Agents and Claude Security clear together or in stages, and whether Microsoft restores the 365 connector path. Docs, Sheets and Meetings belong to the office-suite surface covered in our earlier report on that suite, so their return will show up first in connector telemetry, the same reconciliation problem covered in Anthropic Usage Dashboards Errored Twice in a Day.
For agent fleets the operator lesson is narrower than “Anthropic had a bad day”. Recovery is reported per surface, before it is confirmed, and it can be revoked within minutes. Build lanes so each knows which surface it depends on, what failure class it is facing, and when to stop retrying.