We use cookies to measure how the site is used and how our ads perform (Google Analytics and Ads, Microsoft Clarity, and the Meta, OpenAI and X ad pixels). “Essentials only” turns off advertising cookies everywhere, and analytics too in the EEA, UK and Switzerland. Privacy Policy
Anthropic closed its second Nasdaq session at $88.30, about 6% over its $83 offer price, as the Nasdaq erased 2026. What the rout changes for AI capital.
Qwen Code v0.28.3 adds GitHub and Teams managed channels, private PR-watch wakes on CI failure and idle session suspension. What to switch on, off and measure.
AWS Quick now builds flow automation from a chat description, runs several agents on one request, and adds admin guardrails. What operators can do with it, plus same-day KV caching and HyperPod news.
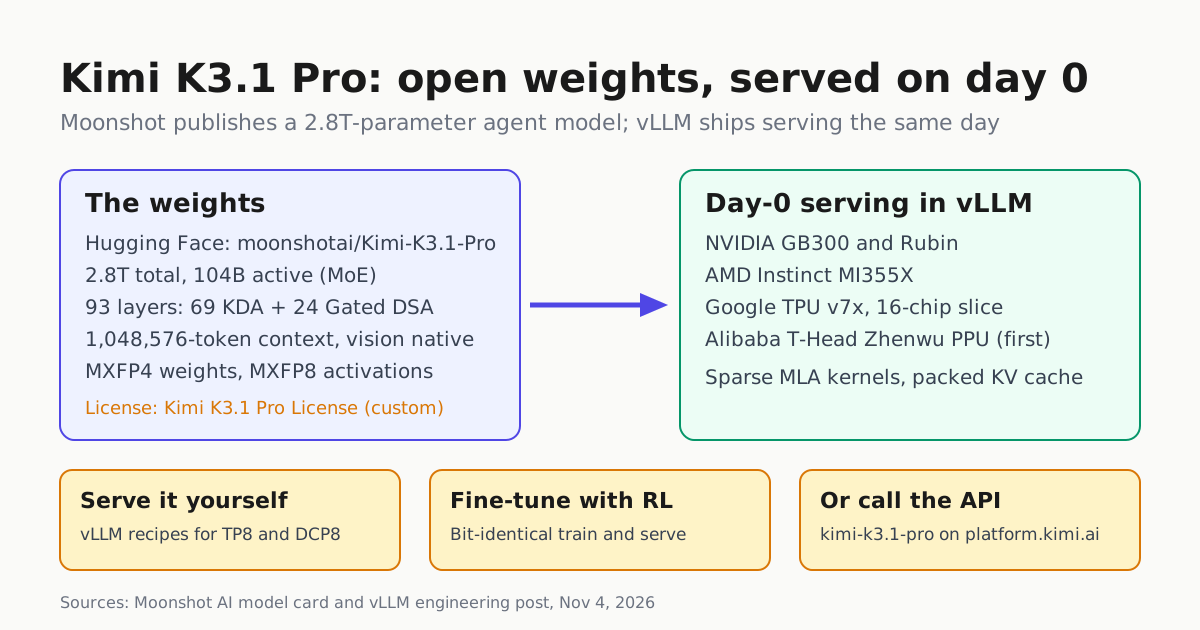
Moonshot AI released Kimi K3.1 Pro open weights: a 2.8T-parameter, 104B-active, 1M-context multimodal agent model under a custom license. vLLM shipped day-0 serving on NVIDIA, AMD, TPU and Alibaba PPU hardware, plus a zero-mismatch RL path.
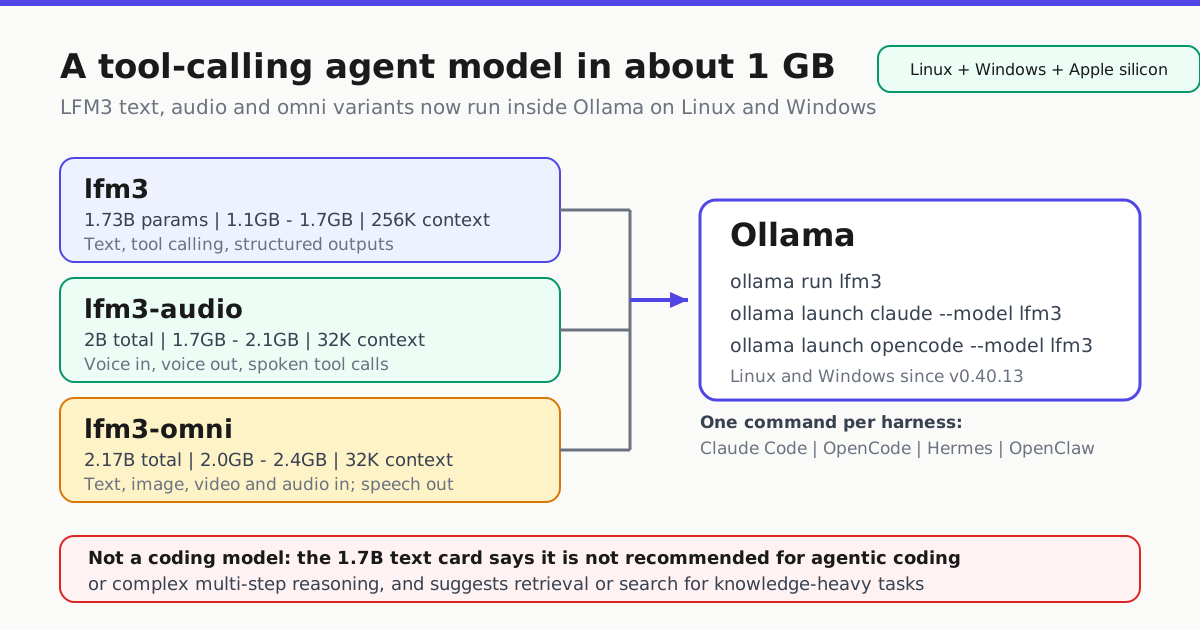
Ollama v0.40.13 adds Linux and Windows support for Liquid AI's LFM3 family. The 1.7B text model calls tools at a 1.1GB-1.7GB download with a 256K window, and Ollama can launch it straight into Claude Code, OpenCode and OpenClaw.
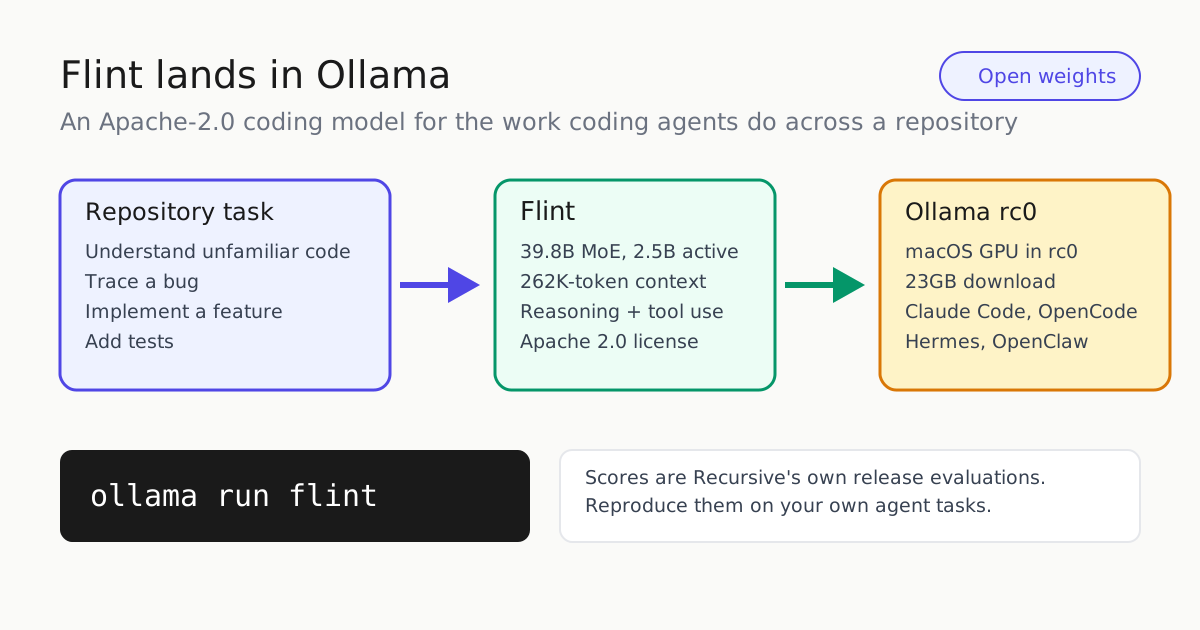
Ollama's v0.40.8-rc0 pre-release adds Recursive's Flint: an Apache-2.0, 39.8B-parameter MoE with about 2.5B parameters active per token, a 262K-token context and day-zero launch lines for Claude Code and OpenCode. What local agent operators should verify before giving it a default slot.
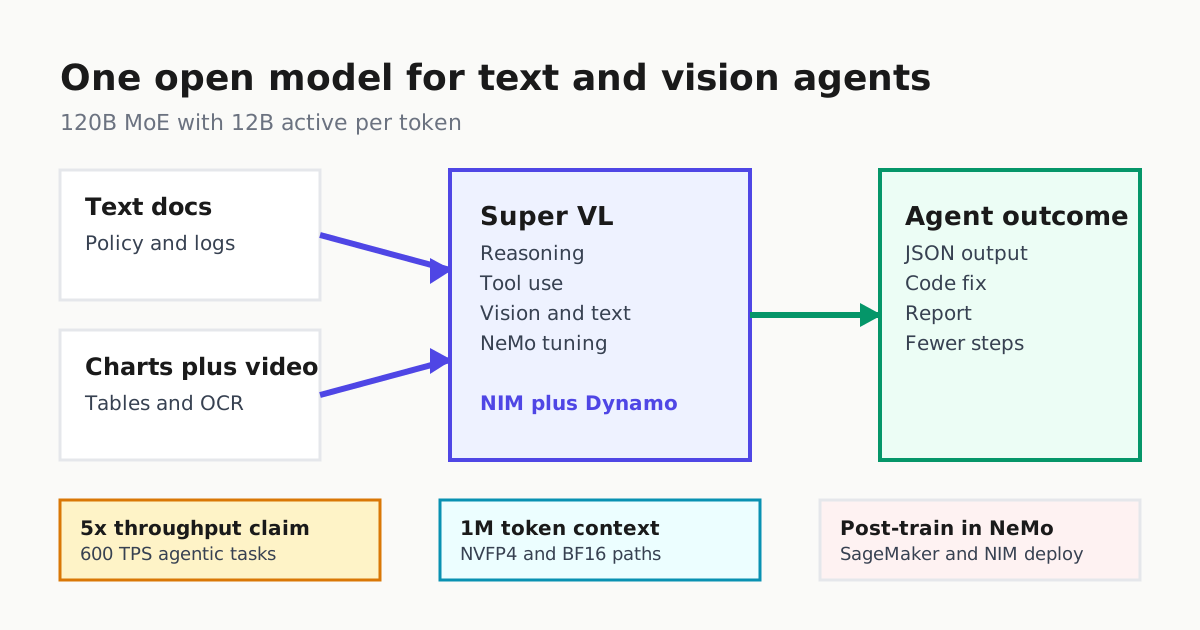
NVIDIA's open 120B Nemotron 3.5 Super VL unifies text and vision for specialized agents, with NeMo tuning, NIM serving and SageMaker day-zero deploy options.
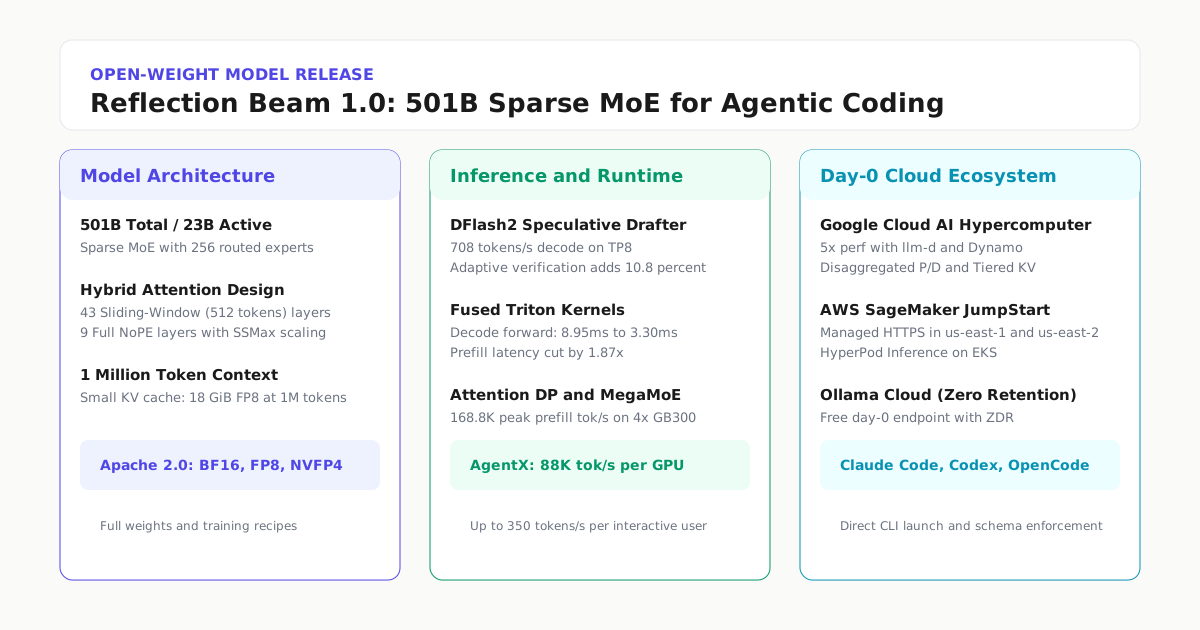
Reflection AI has released the open weights and post-training recipes for Beam, its 501B MoE coding model, under Apache 2.0. Google Cloud, AWS, vLLM, and Ollama delivered day-0 optimizations including DFlash2 speculative decoding, tiered KV caches, and NVFP4 checkpoints.
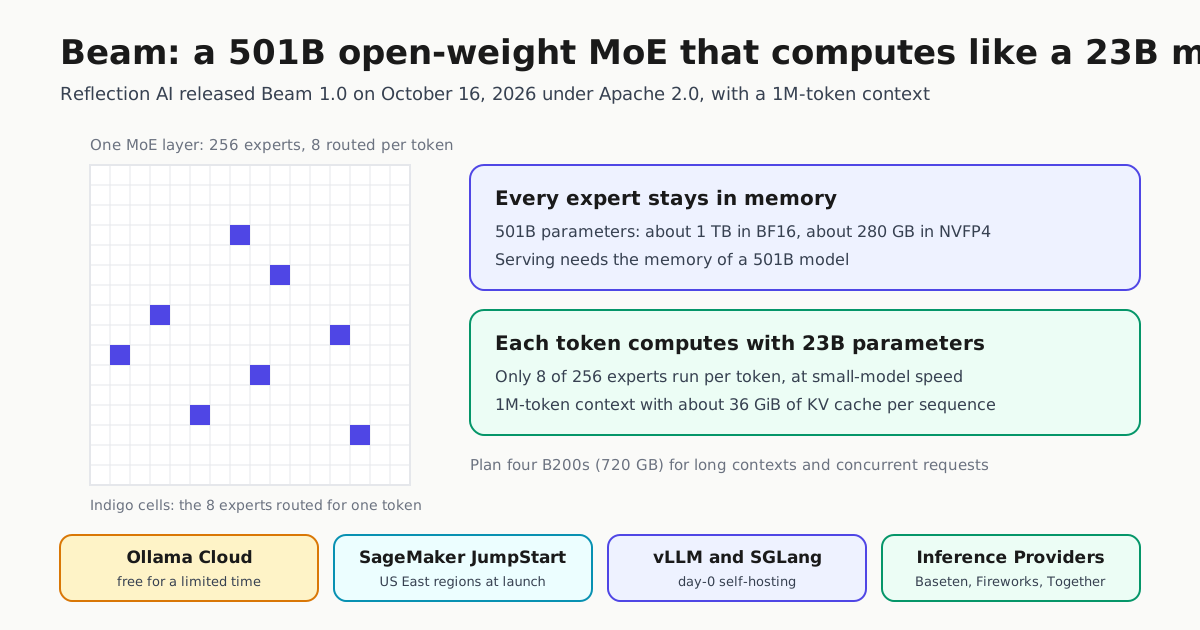
Reflection AI's first model is a 501B-parameter, 23B-active Apache 2.0 MoE with a 1M-token context, built for coding agents. What shipped, what it takes to host, and the four fastest ways to run it today.
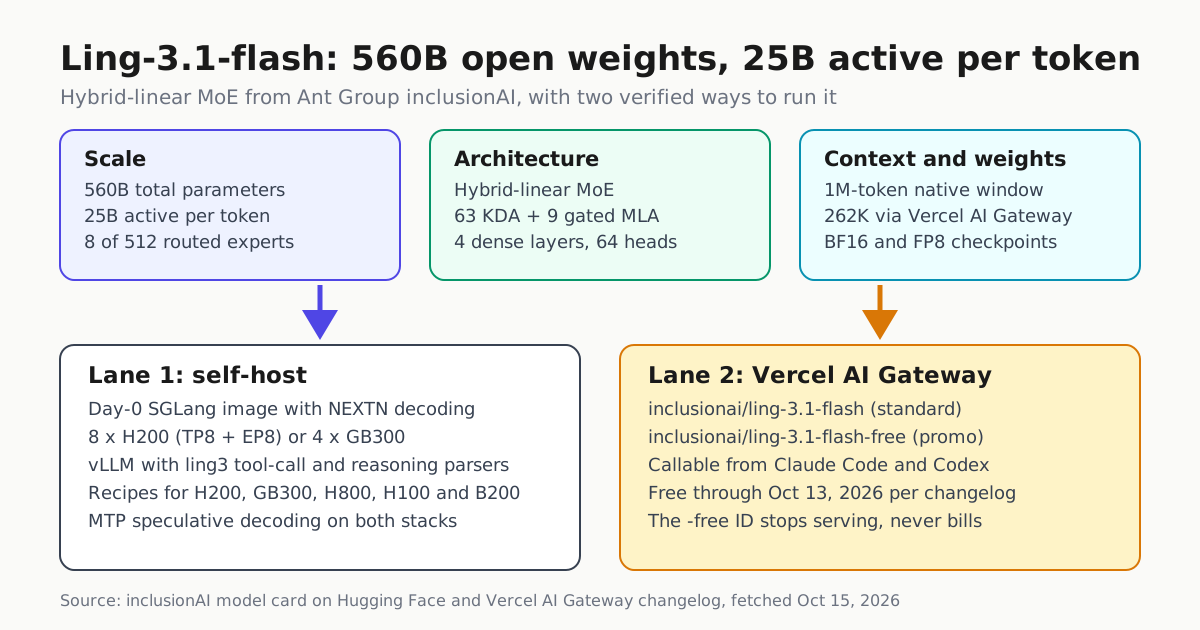
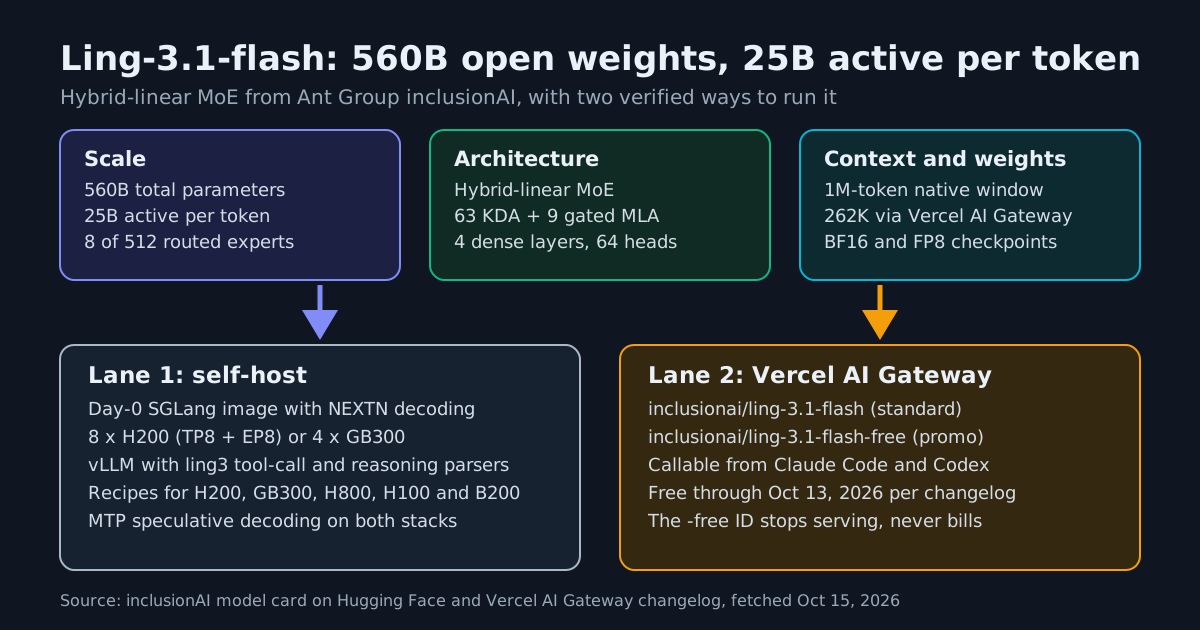
Ling-3.1-flash pairs 560B total and 25B active parameters with a 1M-token native context window, an MIT license badge on its model card, day-0 SGLang and vLLM support, and a Vercel AI Gateway model ID callable from Claude Code and Codex. Verified specs, recipes and chronology.
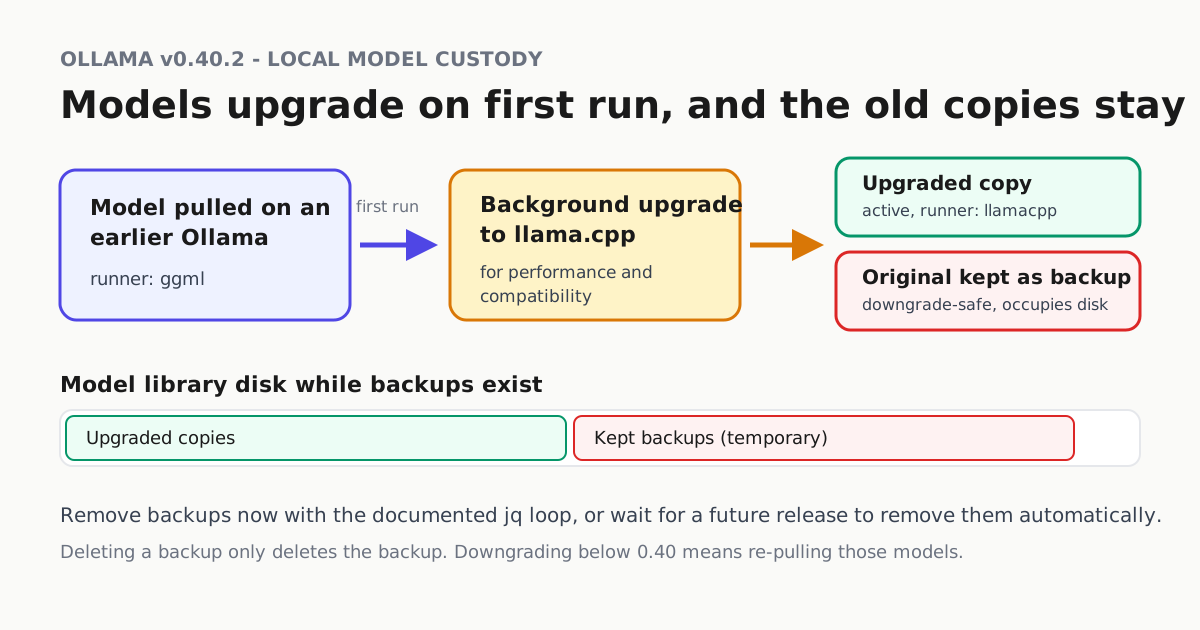
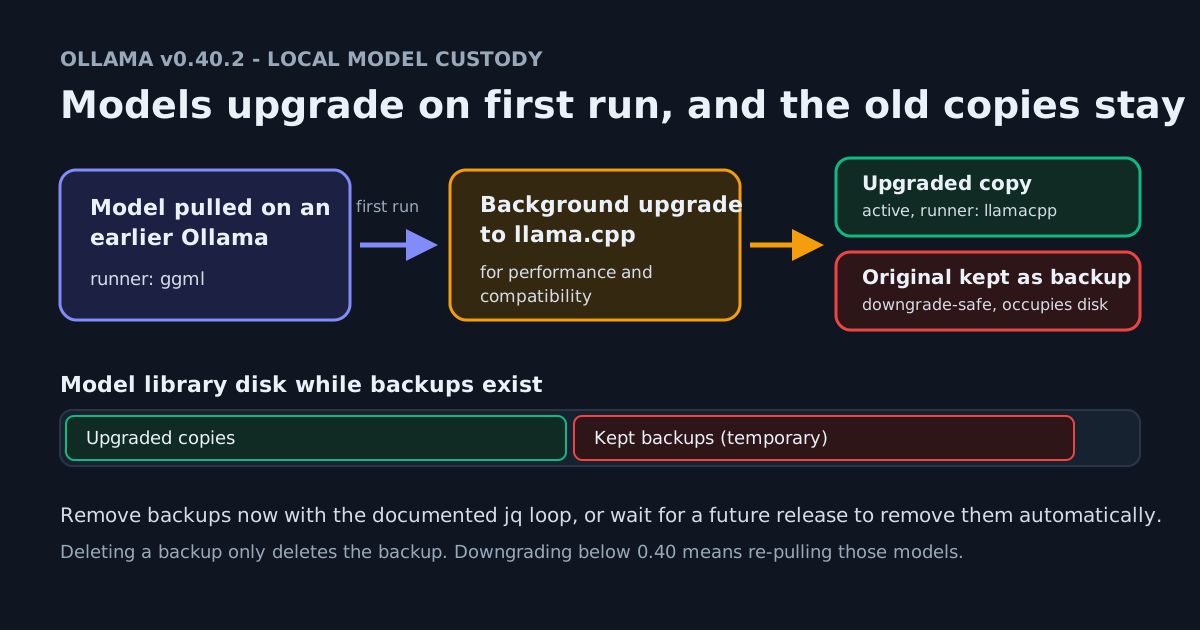
Ollama v0.40.2 upgrades models pulled on earlier versions to llama.cpp in the background the first time they run, and keeps the originals as backups. What that means for disk budgets, safe downgrades, canarying local fleets and the documented jq cleanup loop.
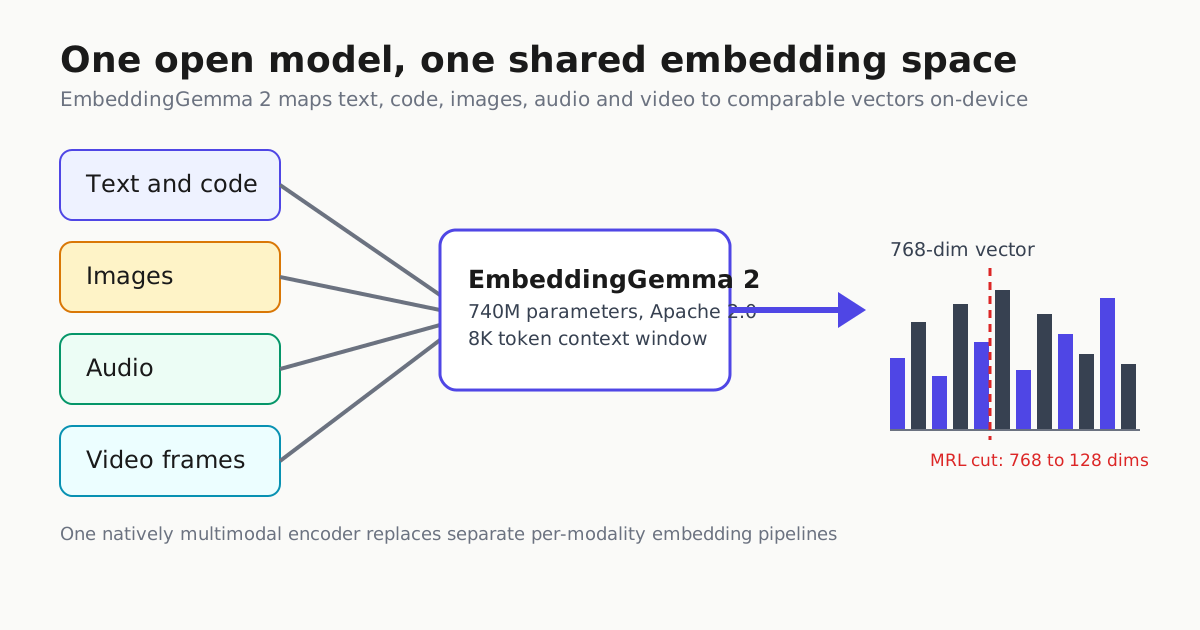
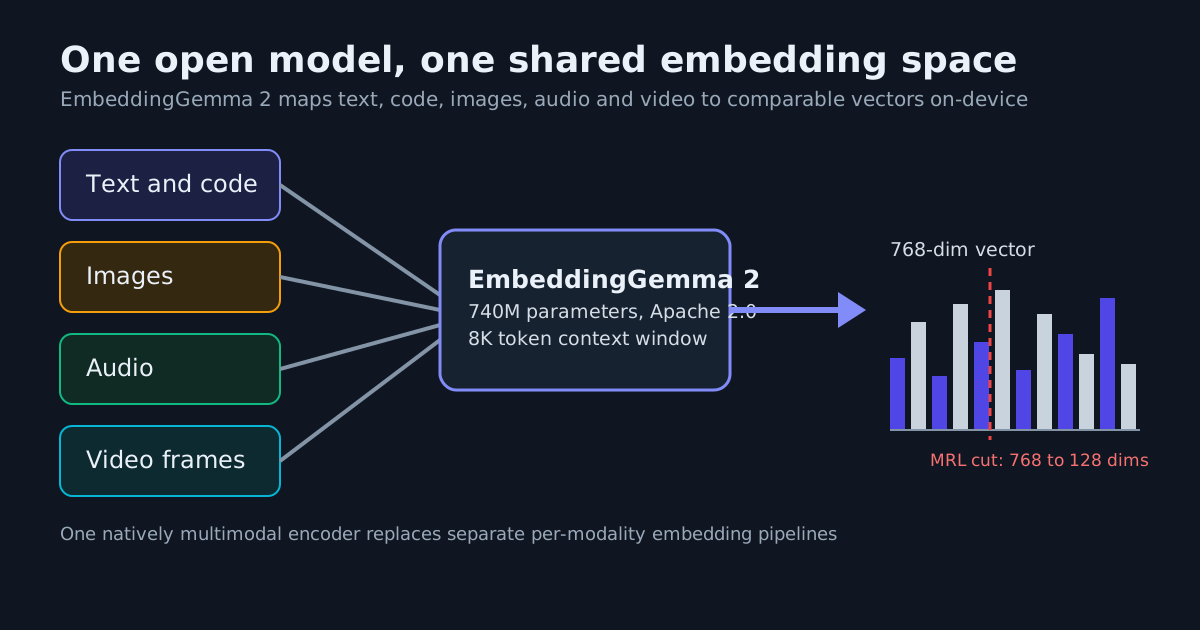
Google DeepMind's EmbeddingGemma 2 maps text, code, images, audio, and video into one 740M-parameter Apache 2.0 embedding space that runs on a phone. What shipped, what is still promised, and why open weights matter for vector stores.
Mistral launches the API preview for Mistral Large 4, a 1-trillion parameter multimodal model with strong performance in cybersecurity and agentic coding. Open weights drop soon.