
Google Ships Gemini 4 Neon: A $3/$15 Mid-Tier Frontier Model for Agentic Coding, Already in Copilot
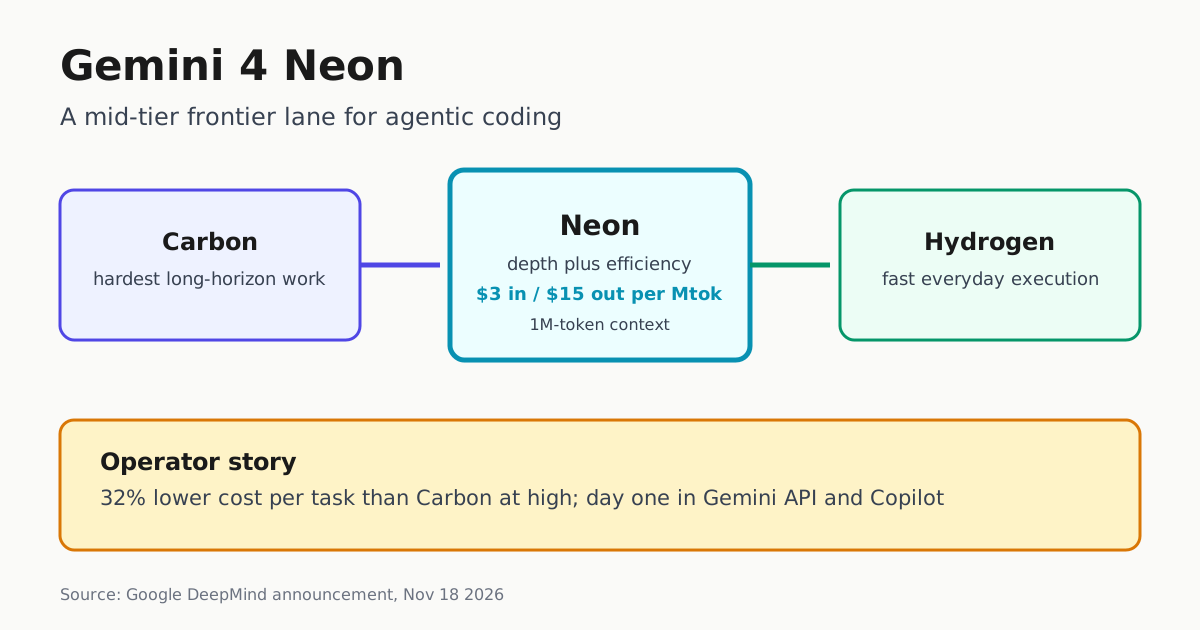
Gemini 4 Neon slots between Carbon and Hydrogen at $3/$15 per million tokens with a 1M context, live day one in the Gemini API and GitHub Copilot.
We use cookies to measure how the site is used and how our ads perform (Google Analytics and Ads, Microsoft Clarity, and the Meta, OpenAI and X ad pixels). “Essentials only” turns off advertising cookies everywhere, and analytics too in the EEA, UK and Switzerland. Privacy Policy
AUTOMATER NEWSROOM
New tools, useful workflows, and consequential AI developments.
Subscribe via RSS ↗Anthropic closed its second Nasdaq session at $88.30, about 6% over its $83 offer price, as the Nasdaq erased 2026. What the rout changes for AI capital.
Qwen Code v0.28.3 adds GitHub and Teams managed channels, private PR-watch wakes on CI failure and idle session suspension. What to switch on, off and measure.
AWS Quick now builds flow automation from a chat description, runs several agents on one request, and adds admin guardrails. What operators can do with it, plus same-day KV caching and HyperPod news.
Gemini 4 Neon slots between Carbon and Hydrogen at $3/$15 per million tokens with a 1M context, live day one in the Gemini API and GitHub Copilot.
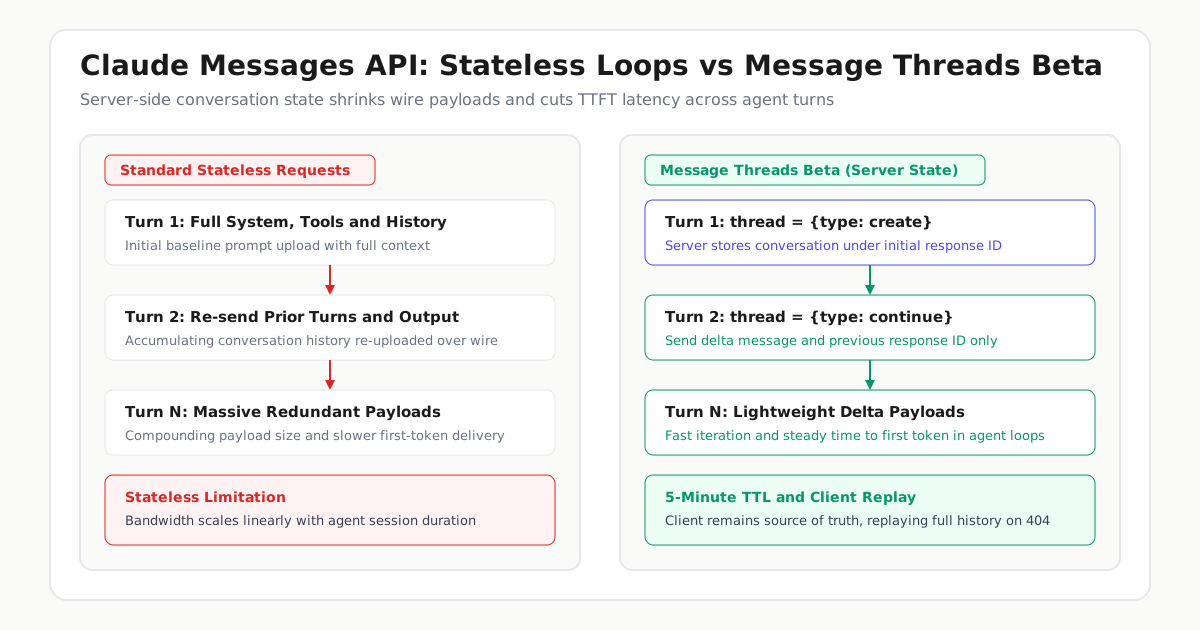
Anthropic launched a Message Threads beta on the Claude Messages API, caching conversation state server-side to shrink payloads and speed up agent loops.
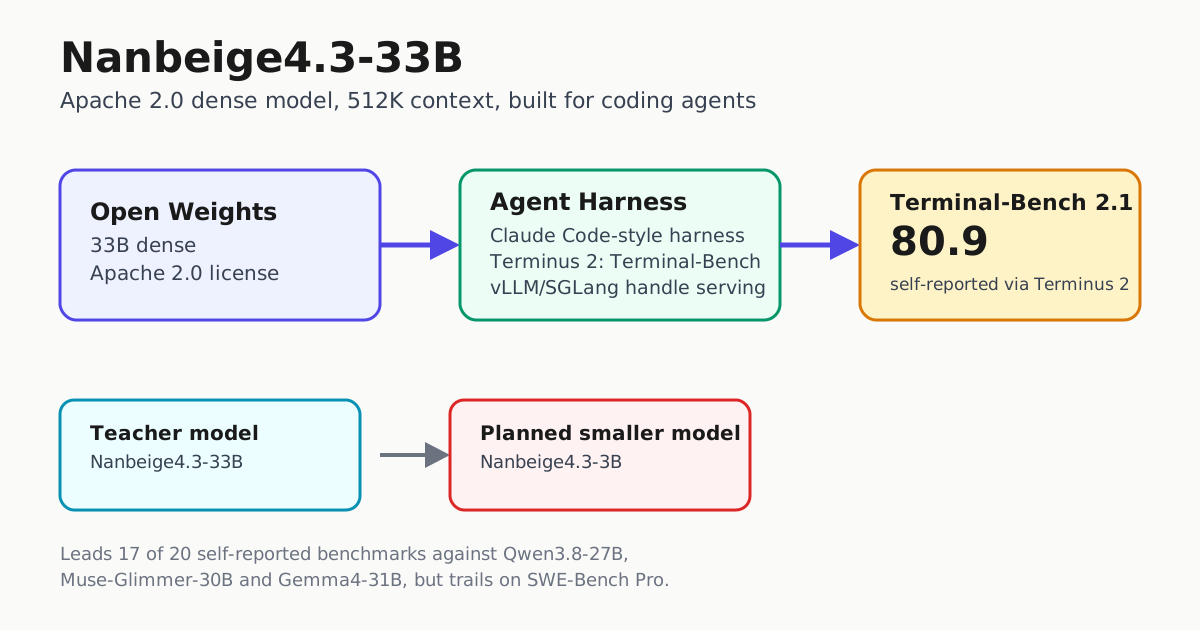
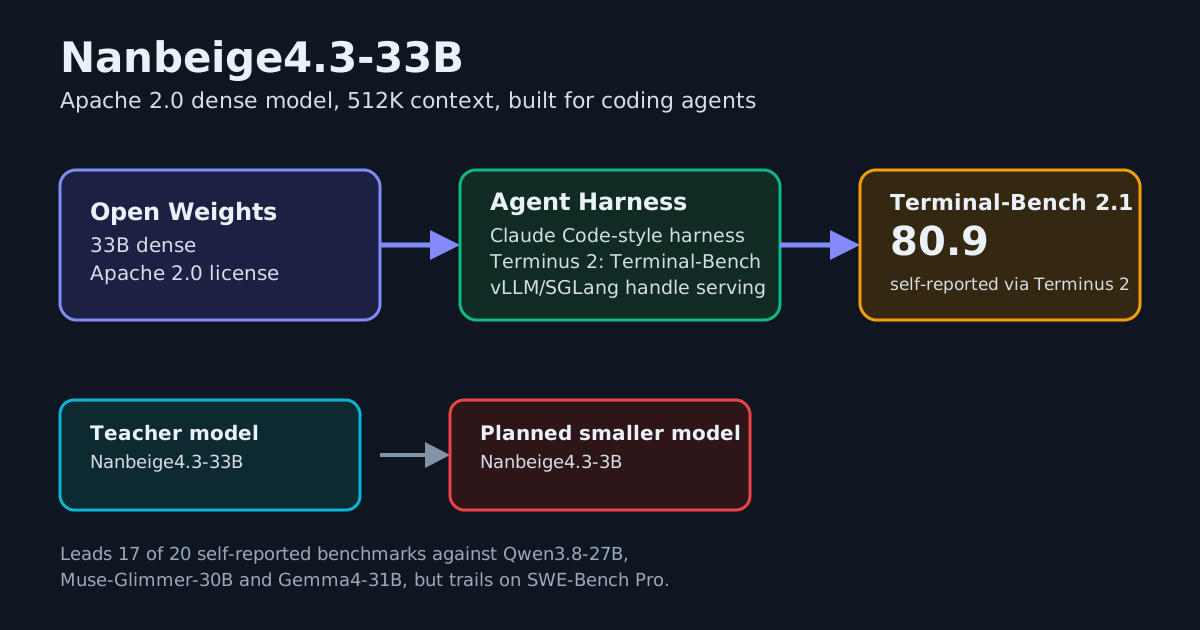
Nanbeige4.3-33B is a 33B dense, Apache 2.0 model with 512K context that claims 17 of 20 wins in a mixed coding, cowork and reasoning benchmark suite against three ~30B open rivals.
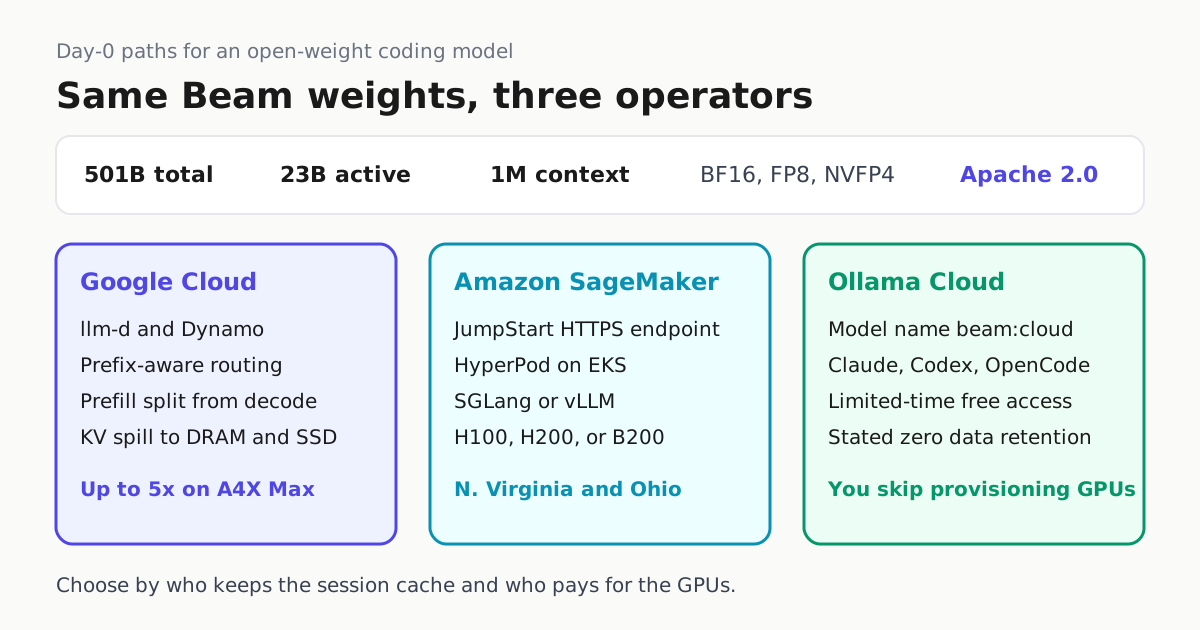
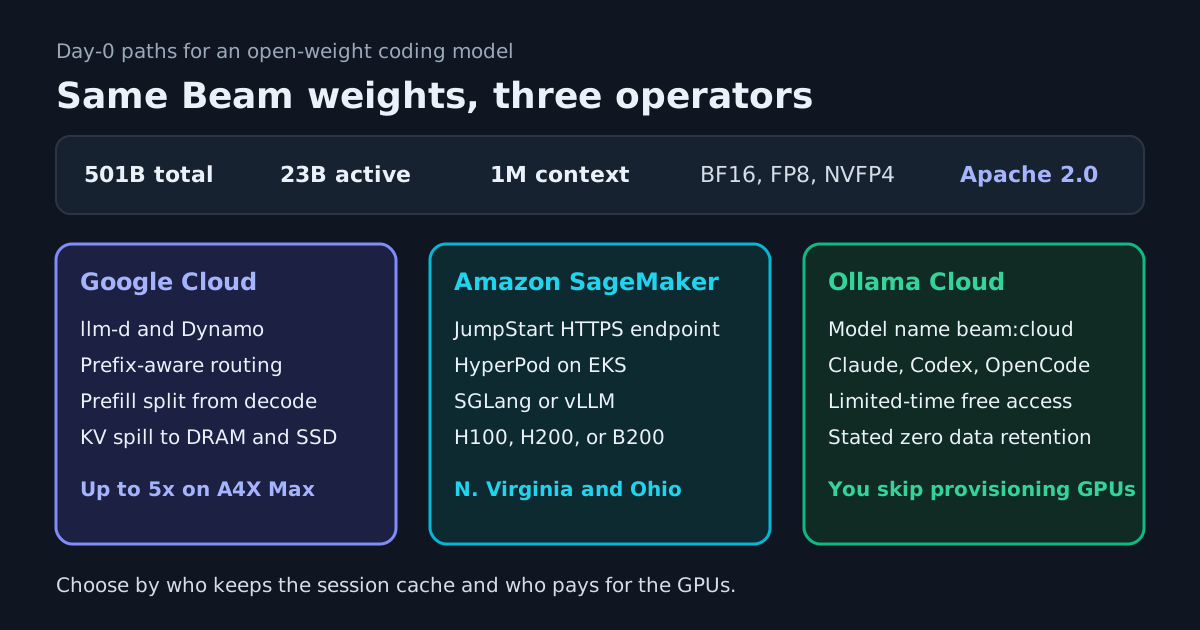
Three October 16 paths to Reflection Beam: Google Cloud cache-aware serving, SageMaker JumpStart and HyperPod, and Ollama Cloud for a limited time with stated zero data retention.
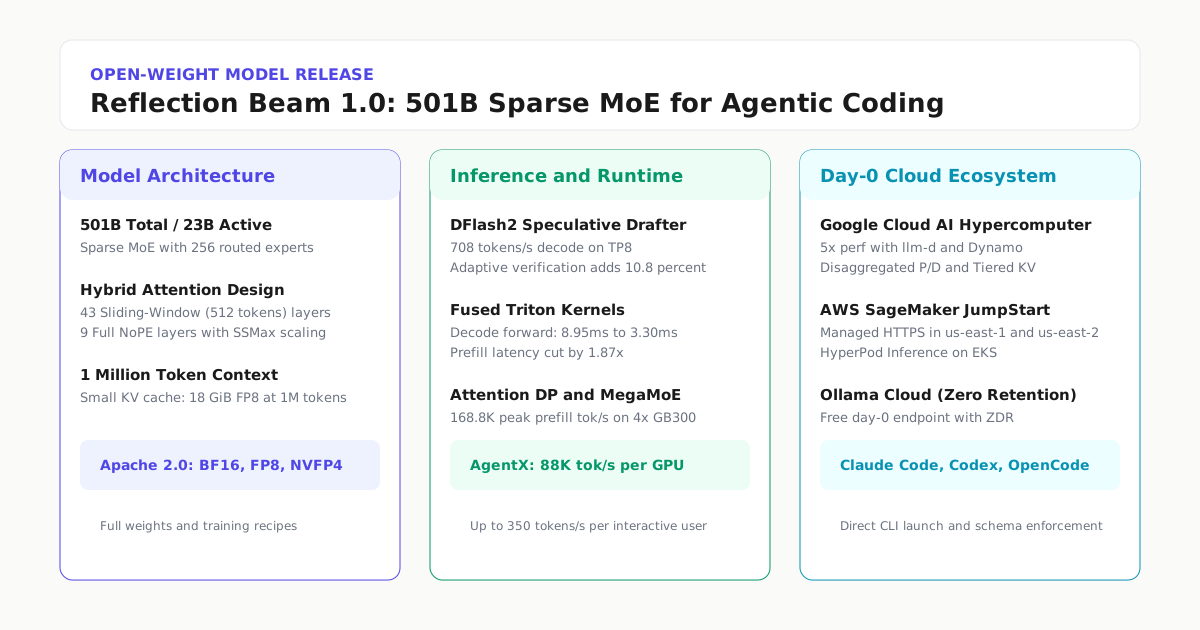
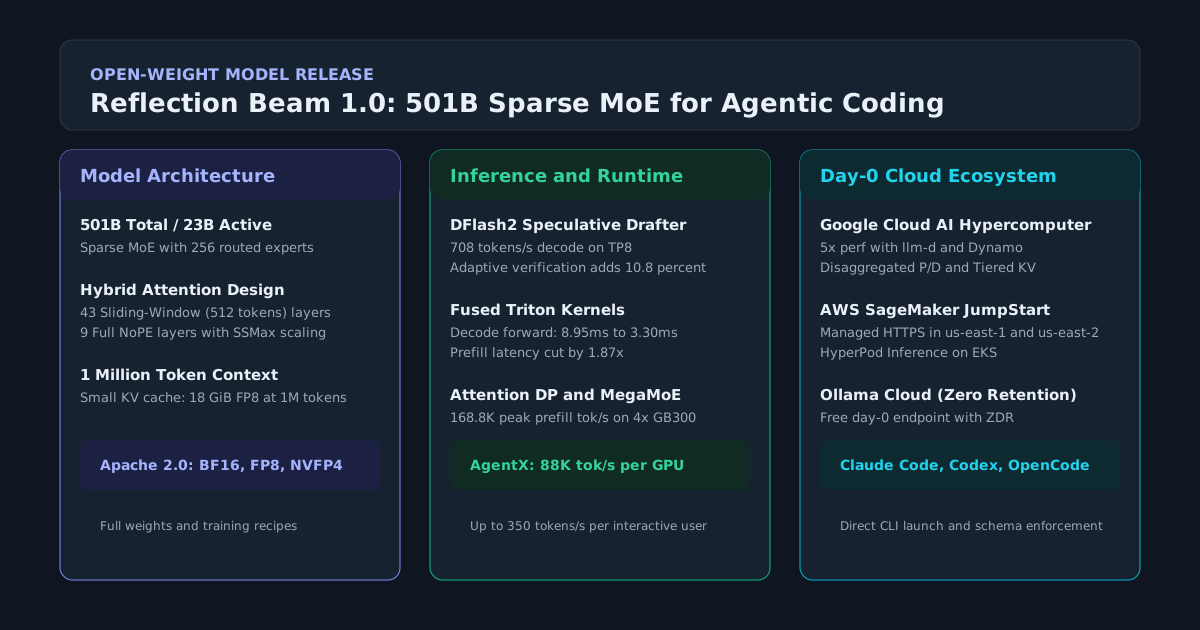
Reflection AI has released the open weights and post-training recipes for Beam, its 501B MoE coding model, under Apache 2.0. Google Cloud, AWS, vLLM, and Ollama delivered day-0 optimizations including DFlash2 speculative decoding, tiered KV caches, and NVFP4 checkpoints.
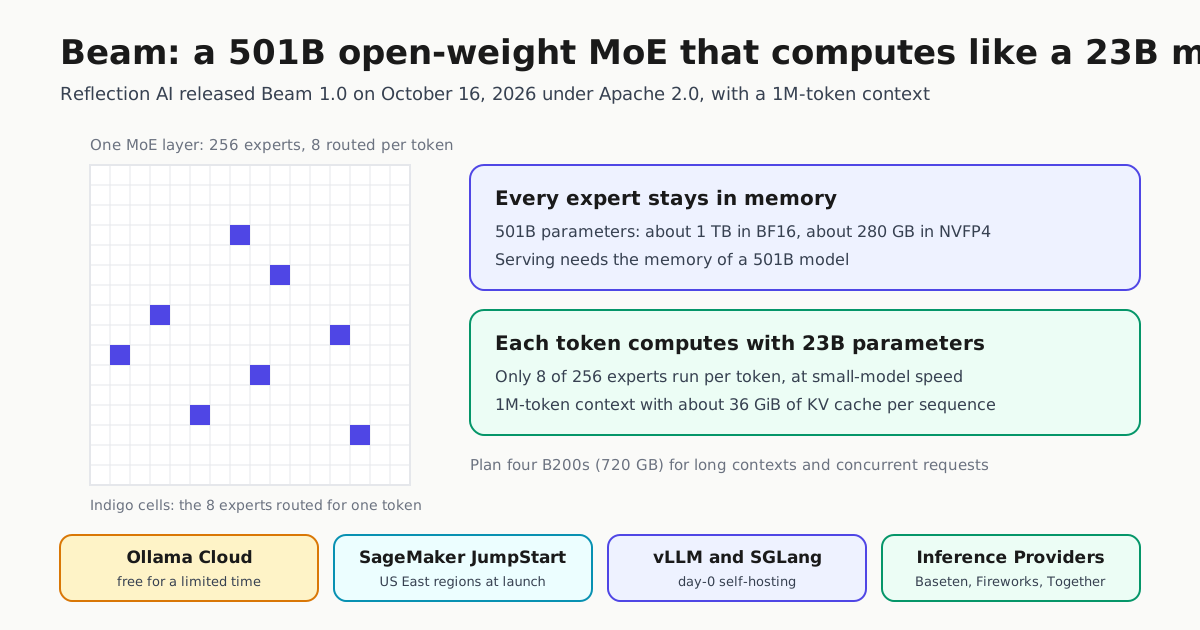
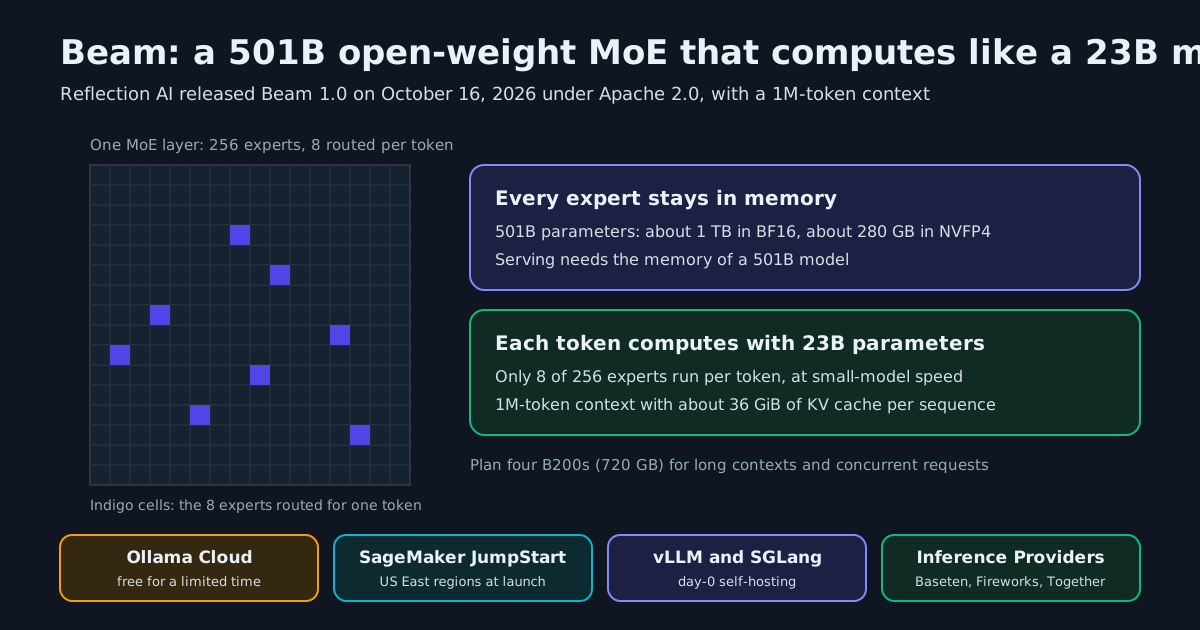
Reflection AI's first model is a 501B-parameter, 23B-active Apache 2.0 MoE with a 1M-token context, built for coding agents. What shipped, what it takes to host, and the four fastest ways to run it today.
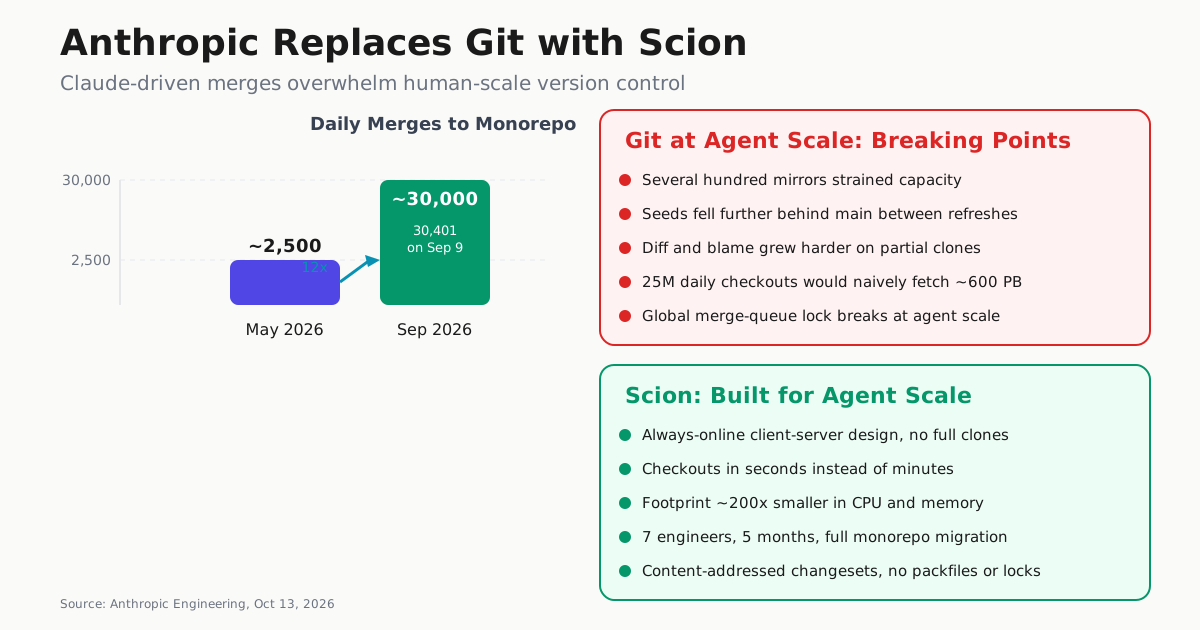
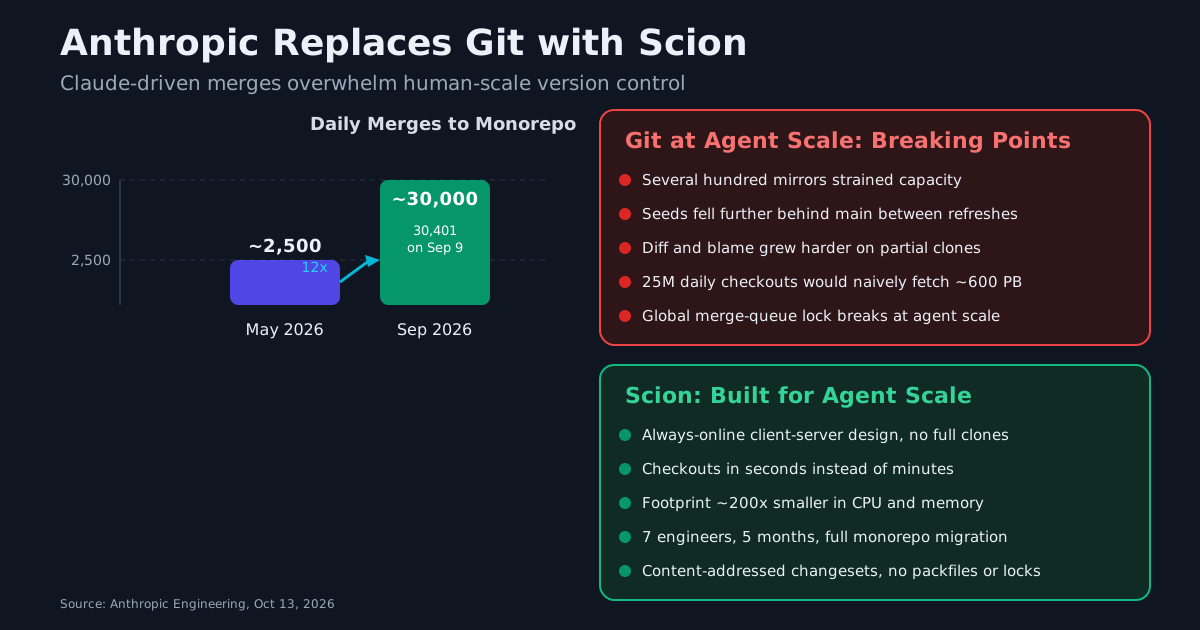
A seven-person team built Scion, an always-online client-server version control system, and migrated Anthropic's entire monorepo from Git in five months after daily merges surged from 2,500 to over 30,000.
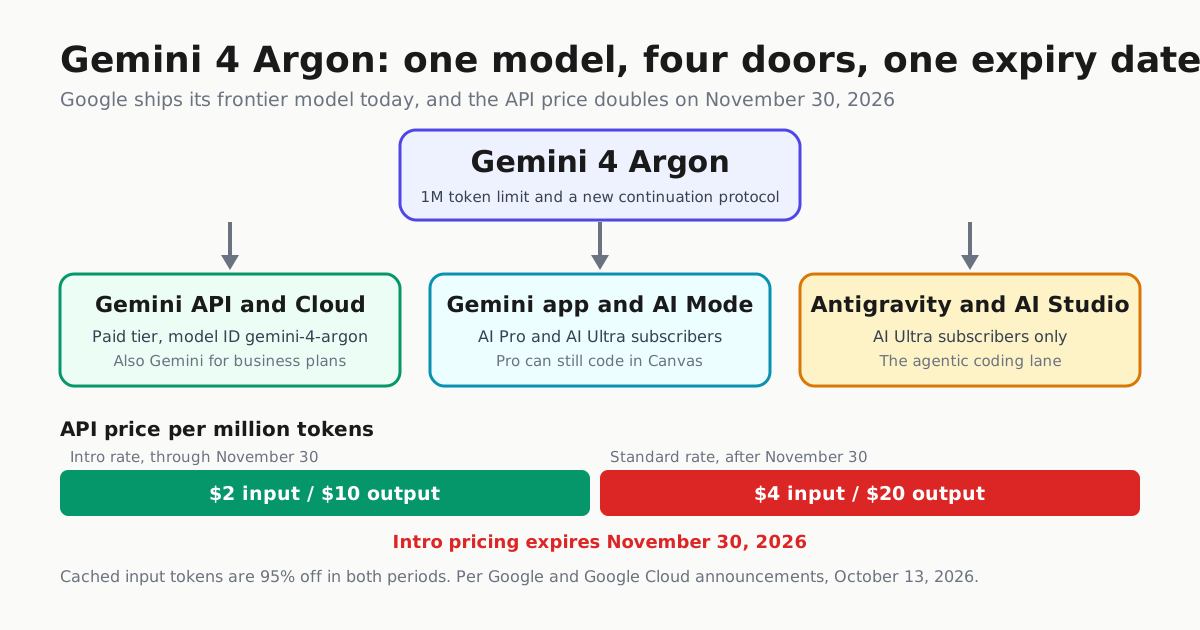
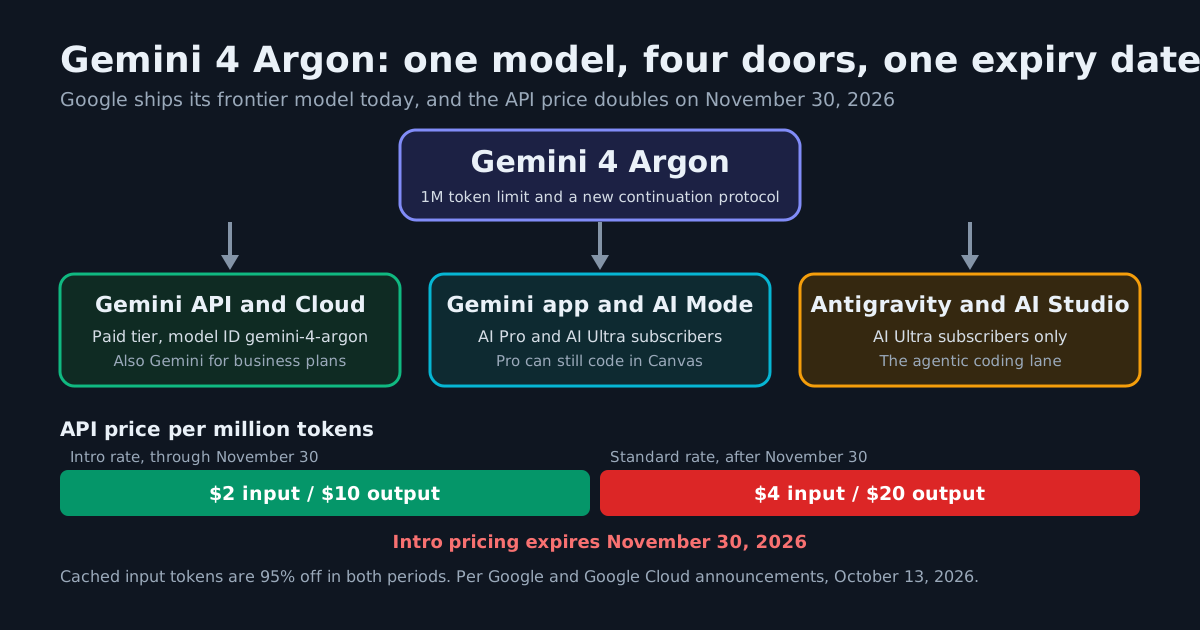
Google's frontier model is live today: paid API lanes get gemini-4-argon, Antigravity stays Ultra-only, the Gemini app needs Pro, and the $2/$10 intro rate per million tokens doubles on November 30, 2026.
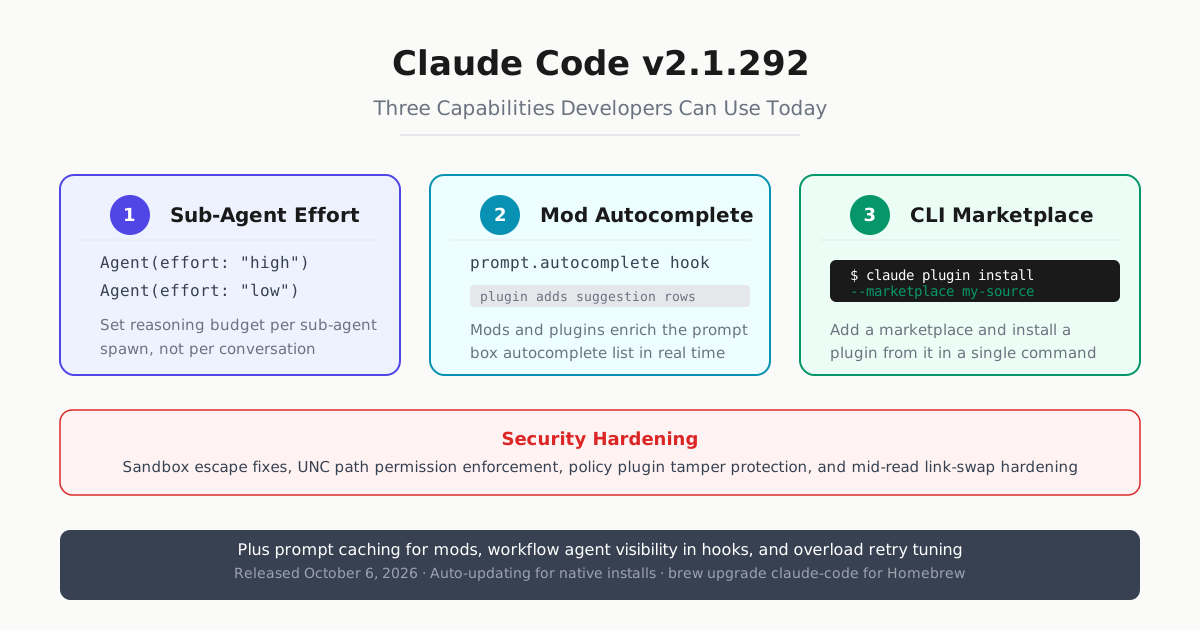
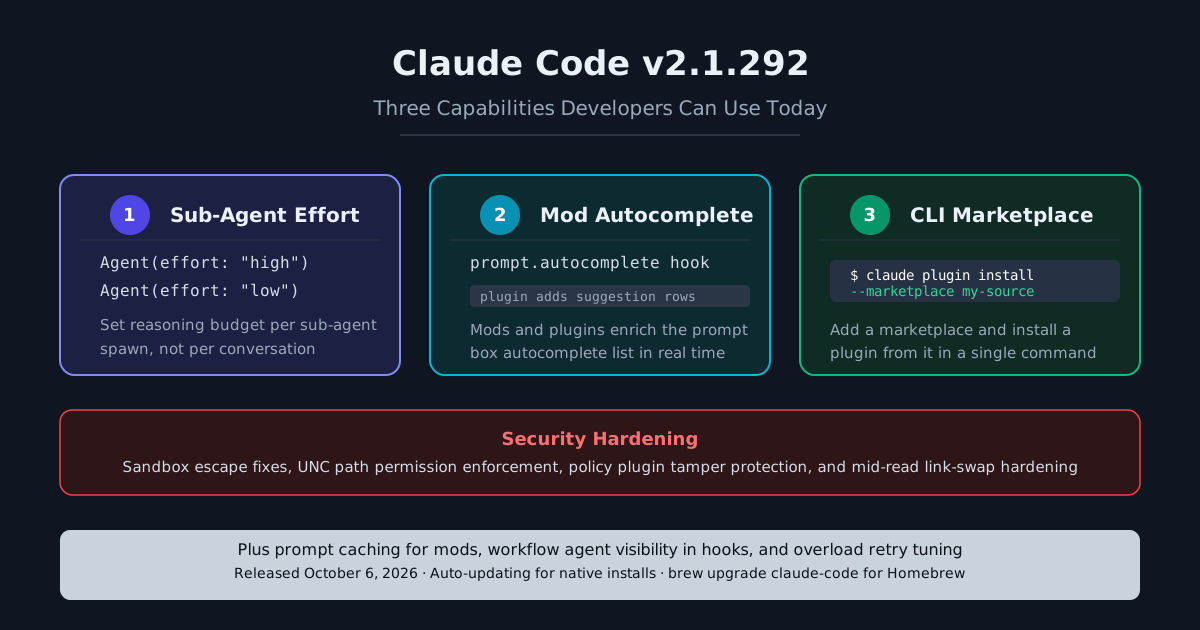
Anthropic ships Claude Code v2.1.292 with per-sub-agent effort budgets, a prompt.autocomplete hook for mods and plugins, --marketplace flag on plugin install, prompt caching for mods, workflow agent visibility in hooks, and critical security fixes for sandbox escapes and UNC path bypasses.
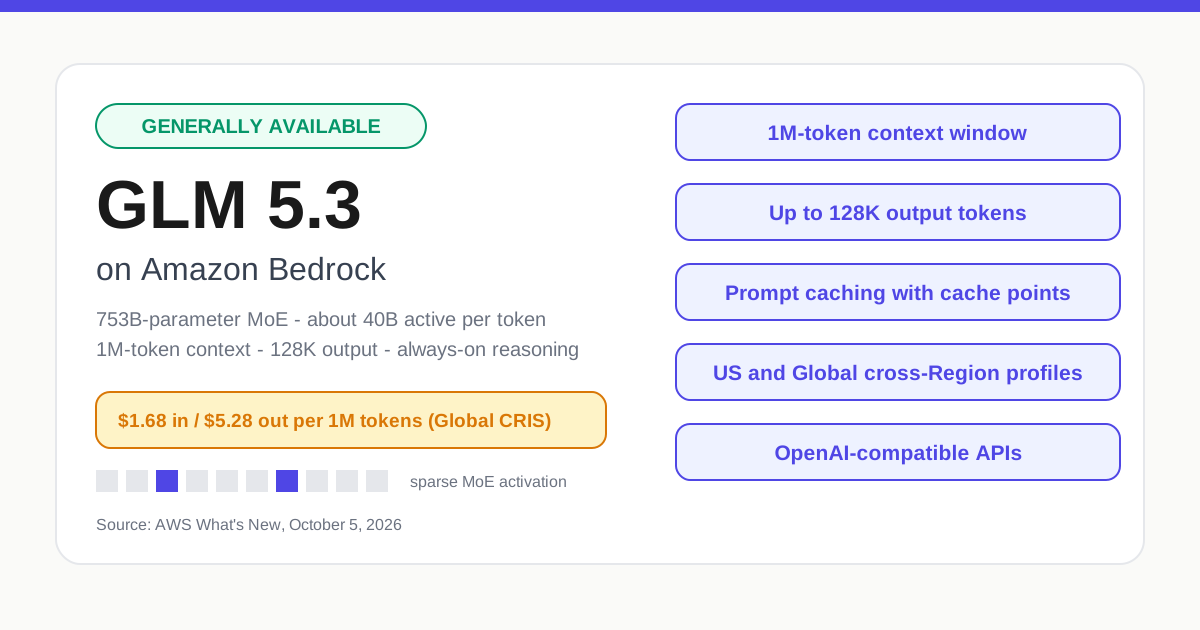
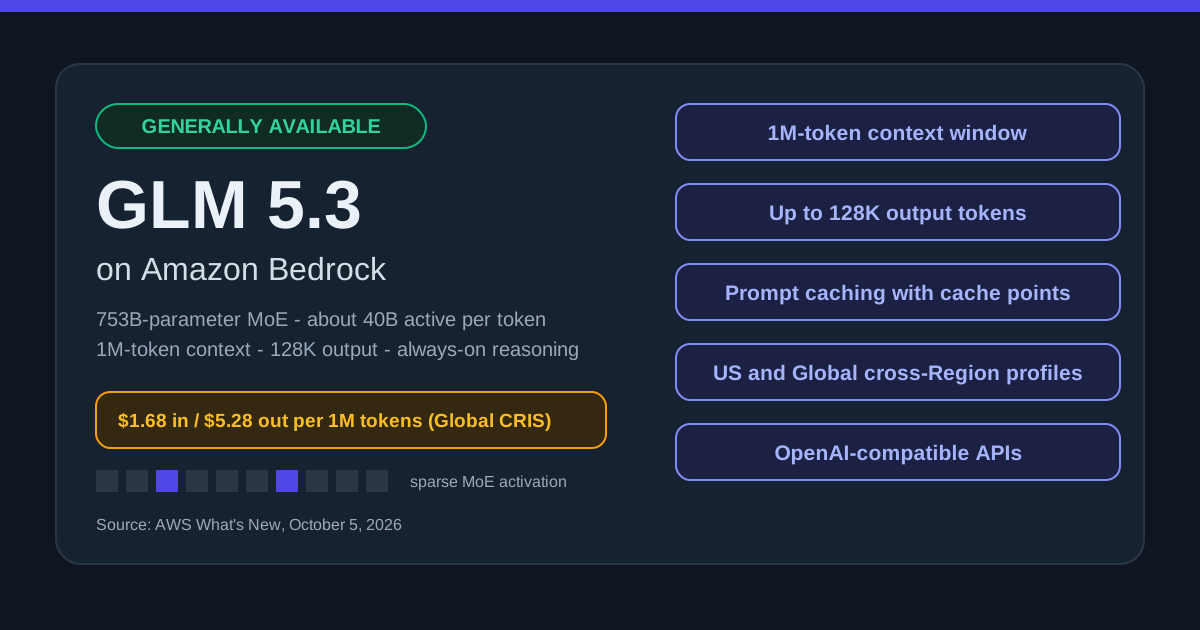
AWS made GLM 5.3 generally available on Amazon Bedrock on October 5, 2026 — managed APIs, cross-Region inference, prompt caching, and $1.68 per 1M input tokens for eligible enterprise customers. What shipped, what it costs, and how to call it.
Our AI-assisted editorial method · Explore our in-depth Intel guides
Get started
Lite is free forever, installs in about a minute, and reads the session history you already have.
Also for macOS (Apple silicon) and Linux.
Signed installer. No account. Session content stays on your disk.
