We use cookies to measure how the site is used and how our ads perform (Google Analytics and Ads, Microsoft Clarity, and the Meta, OpenAI and X ad pixels). “Essentials only” turns off advertising cookies everywhere, and analytics too in the EEA, UK and Switzerland. Privacy Policy
Anthropic closed its second Nasdaq session at $88.30, about 6% over its $83 offer price, as the Nasdaq erased 2026. What the rout changes for AI capital.
Qwen Code v0.28.3 adds GitHub and Teams managed channels, private PR-watch wakes on CI failure and idle session suspension. What to switch on, off and measure.
AWS Quick now builds flow automation from a chat description, runs several agents on one request, and adds admin guardrails. What operators can do with it, plus same-day KV caching and HyperPod news.
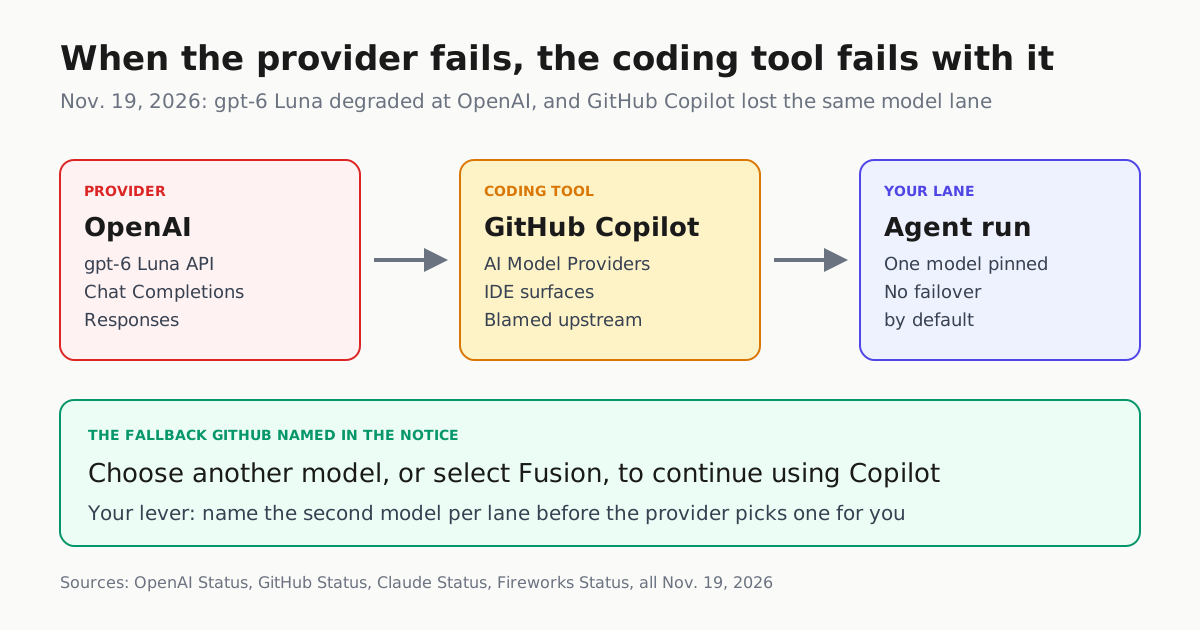
OpenAI's gpt-6 Luna API degraded on Nov. 19, 2026, and GitHub Copilot lost the same model lane, blaming an upstream provider. Four status pages, one day.
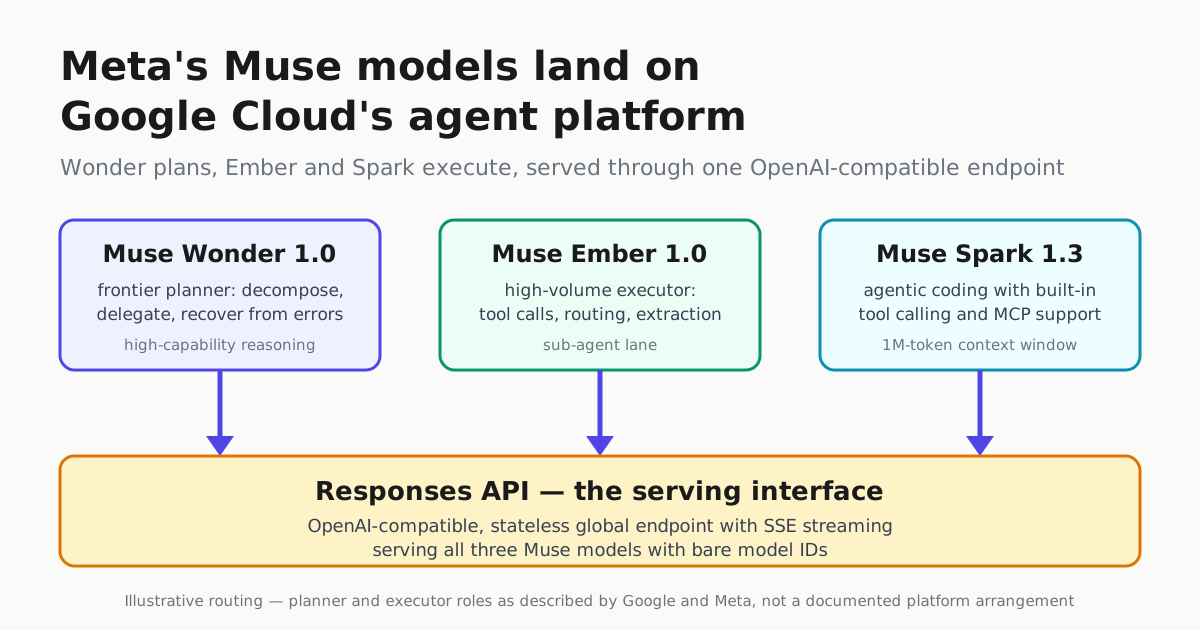
Meta's Muse Wonder, Ember and Spark 1.3 are listed as managed OpenAI-compatible APIs on Google Cloud's agent platform. What they cost, what is unverified, and how to route them.
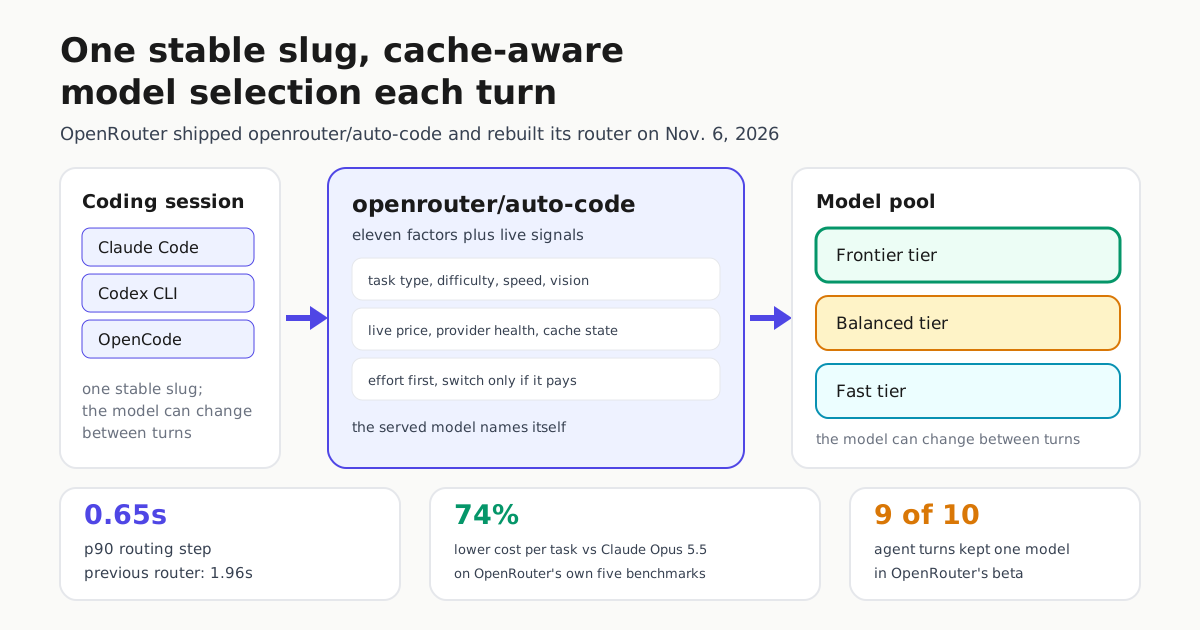
OpenRouter rebuilt its router and shipped openrouter/auto-code for coding agents: eleven request factors, live price, health and cache signals, a 3x faster routing step than the previous router, and 74% lower cost per task than Claude Opus 5.5 on OpenRouter's own five benchmarks.
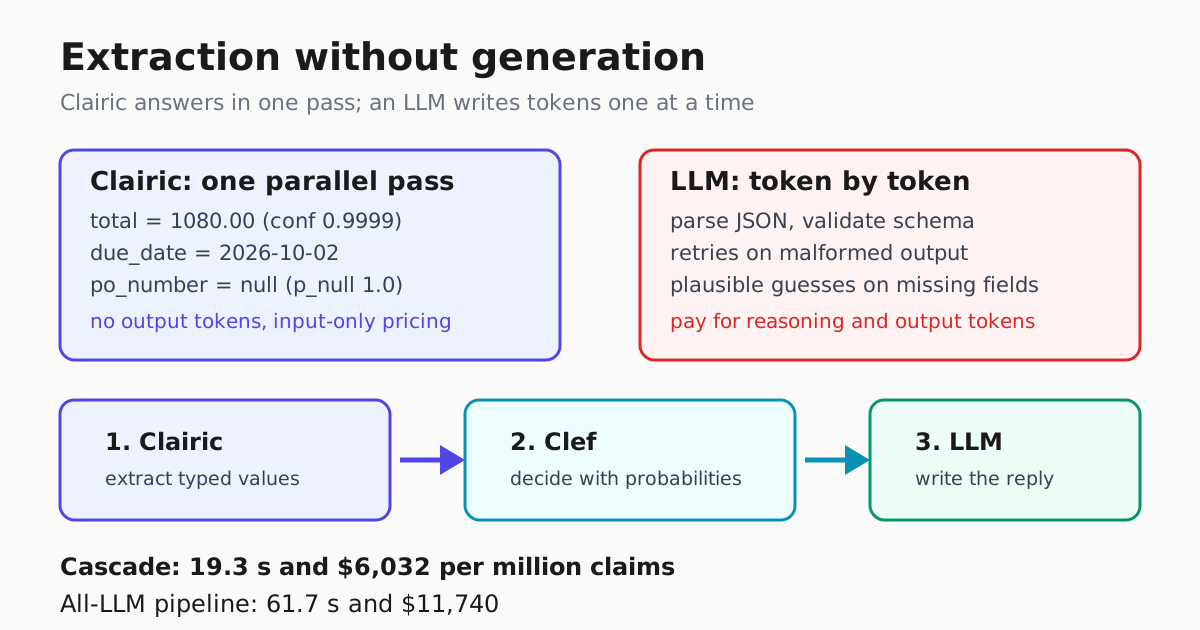
Cloudflare's Clairic extraction model returns typed values with confidence from text and images in one non-generating pass, and its measured cascade beat an all-LLM pipeline 3.2x at 49% lower cost.
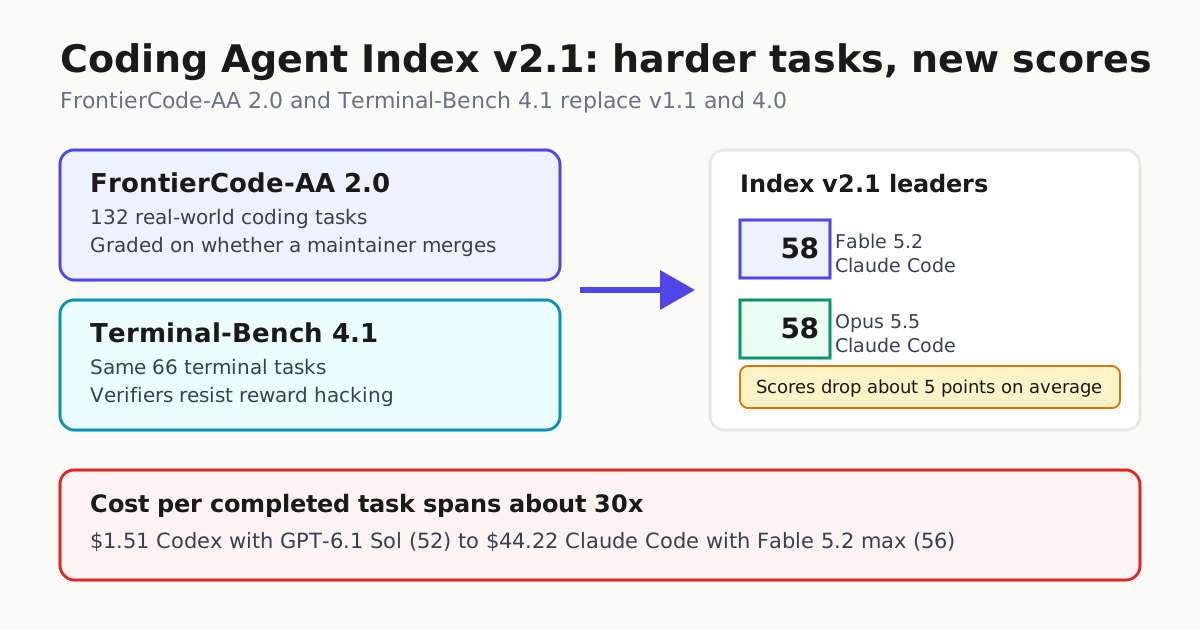
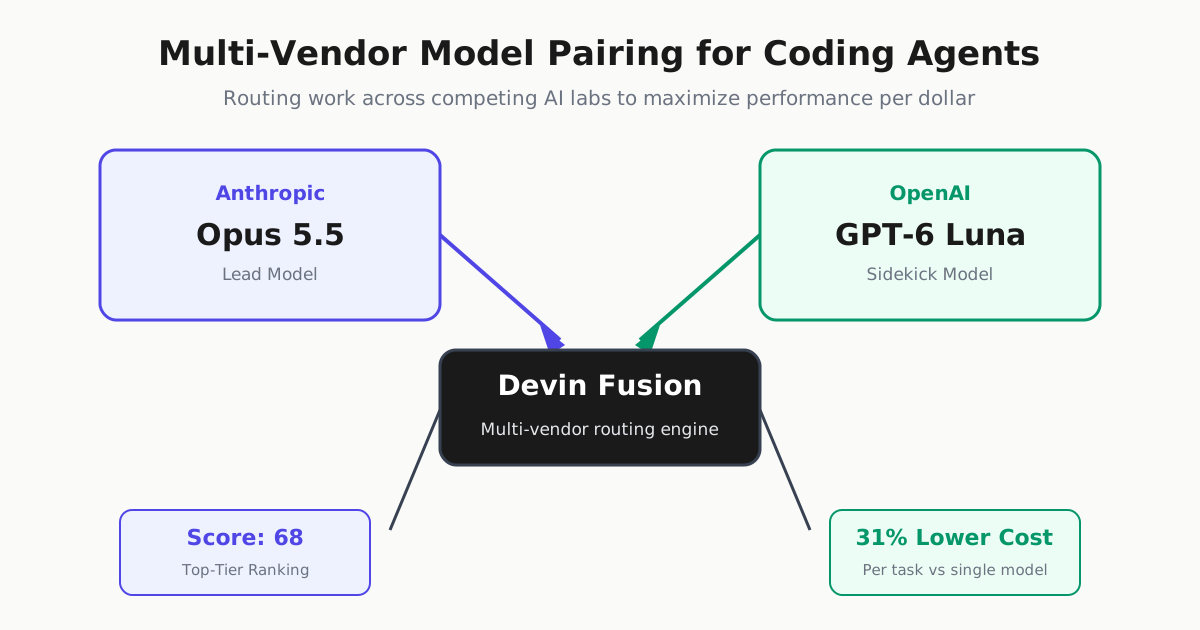
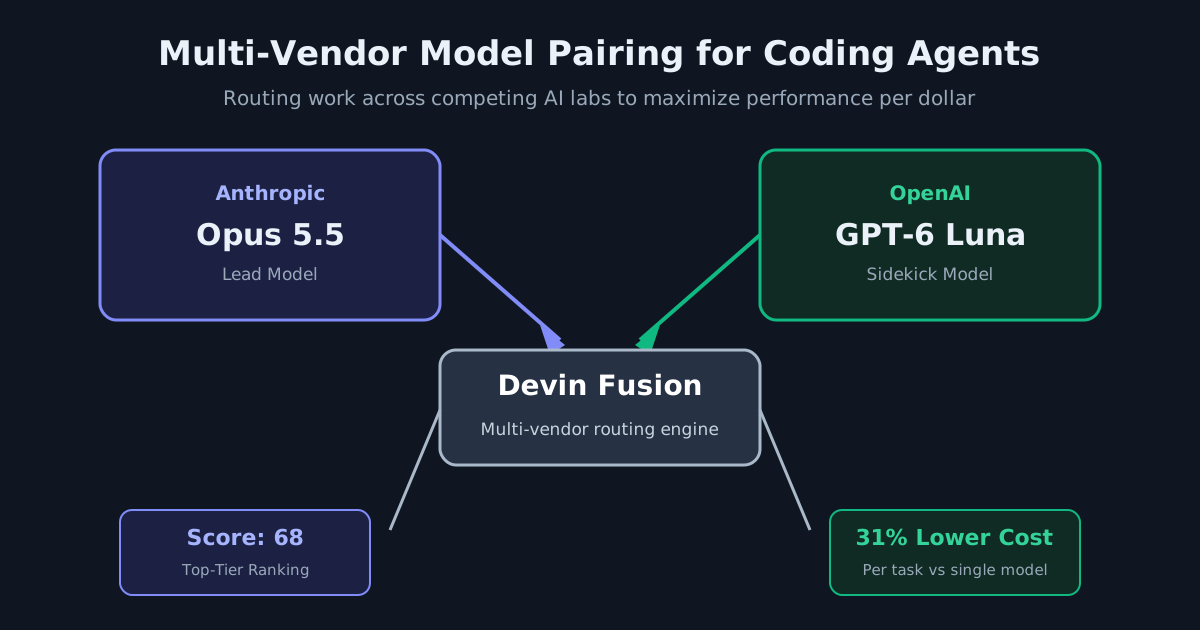
Cognition's Devin Fusion scored 68 on Artificial Analysis' Coding Agent Index using an Opus 5.5 lead and GPT-6 Luna sidekick, claiming 31% lower cost per task than Claude Code alone.
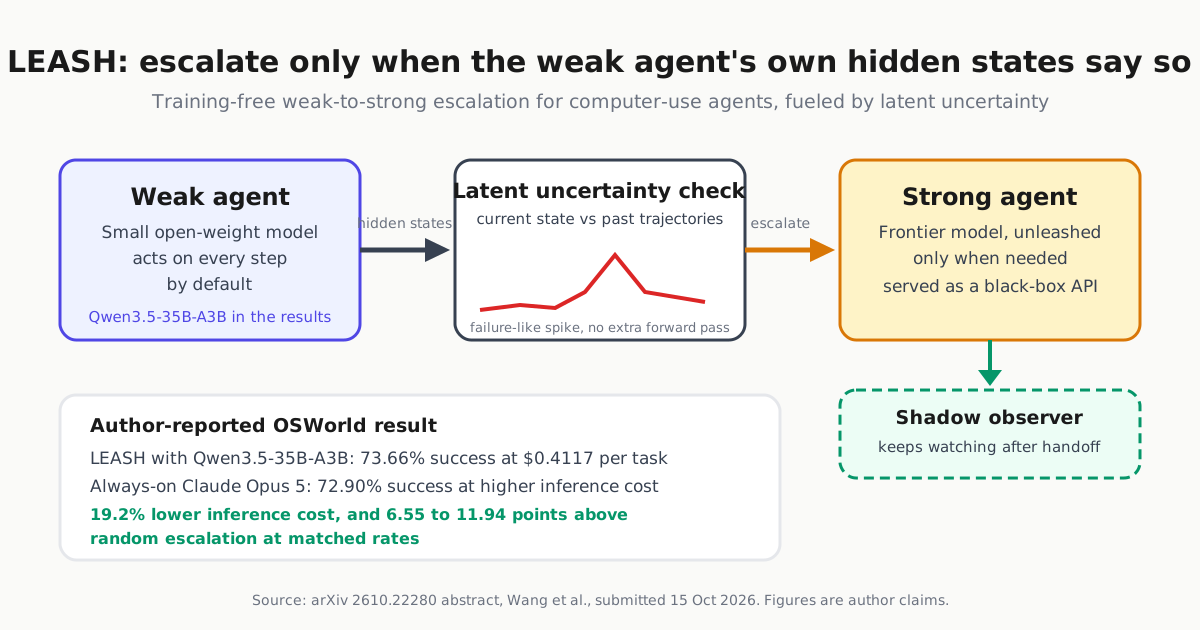
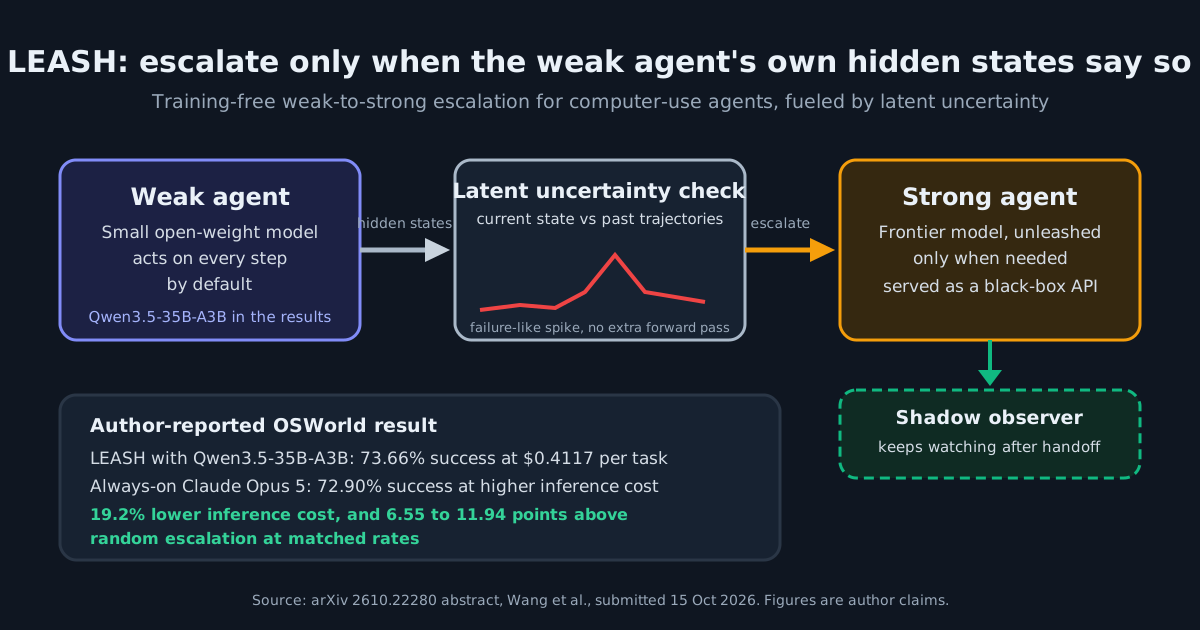
A new arXiv paper keeps a small open-weight agent in control of computer-use tasks and hands off to a frontier model only when the weak model's hidden states resemble past failures. Authors report OSWorld success matching always-on Claude Opus 5 at 19.2% lower inference cost.
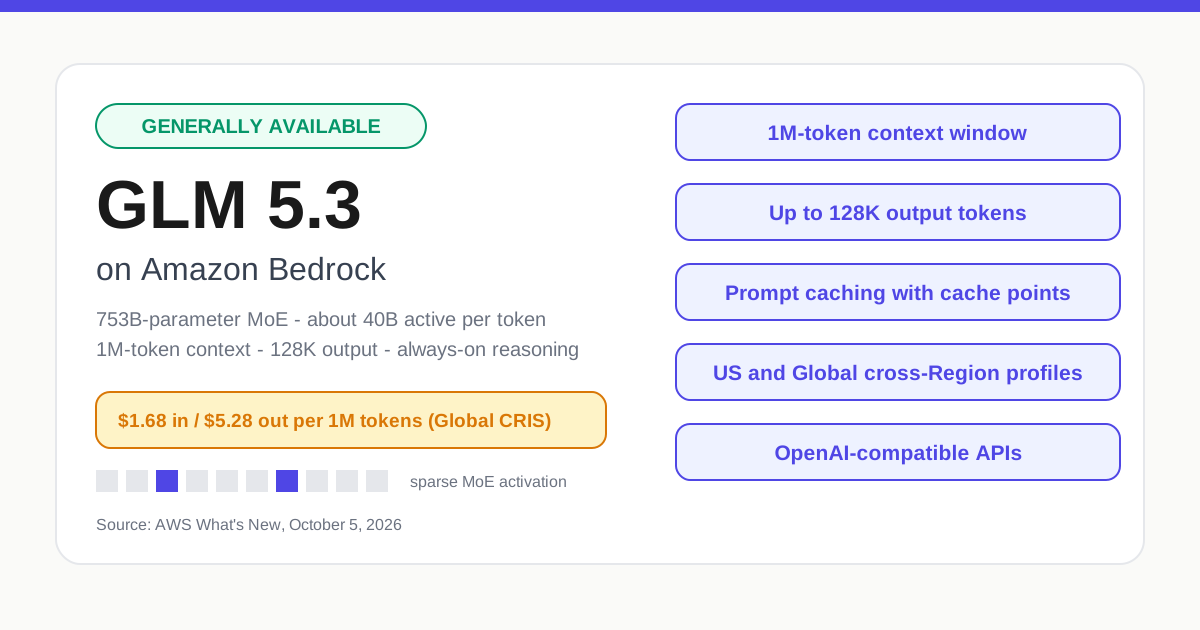
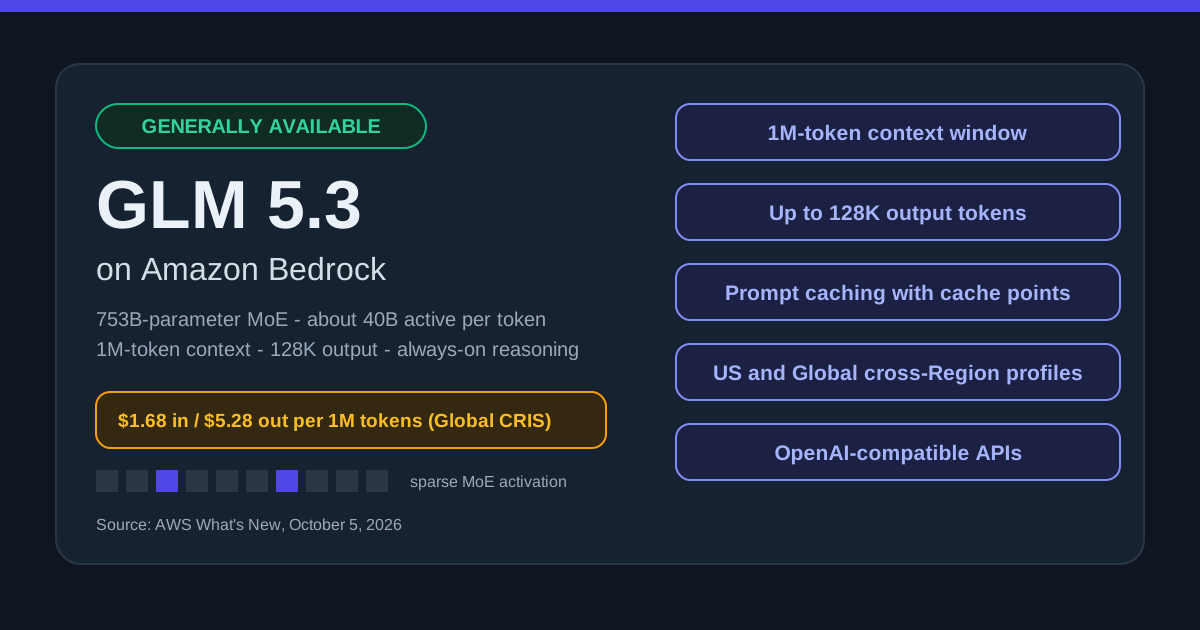
AWS made GLM 5.3 generally available on Amazon Bedrock on October 5, 2026 — managed APIs, cross-Region inference, prompt caching, and $1.68 per 1M input tokens for eligible enterprise customers. What shipped, what it costs, and how to call it.