
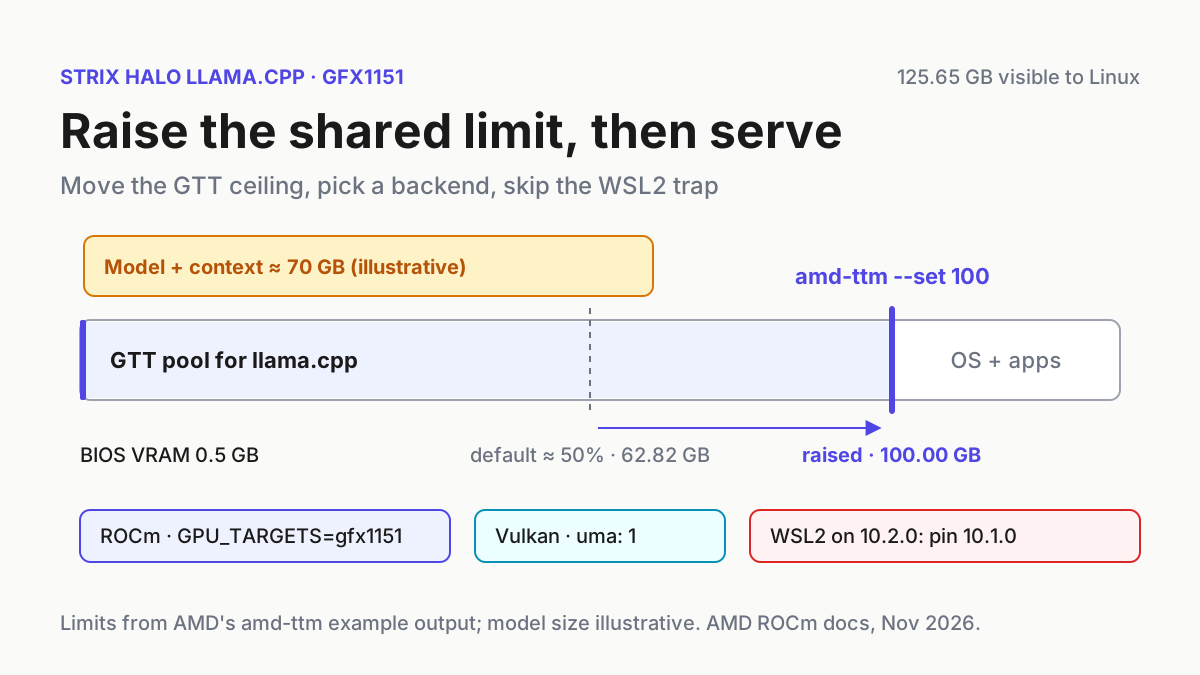
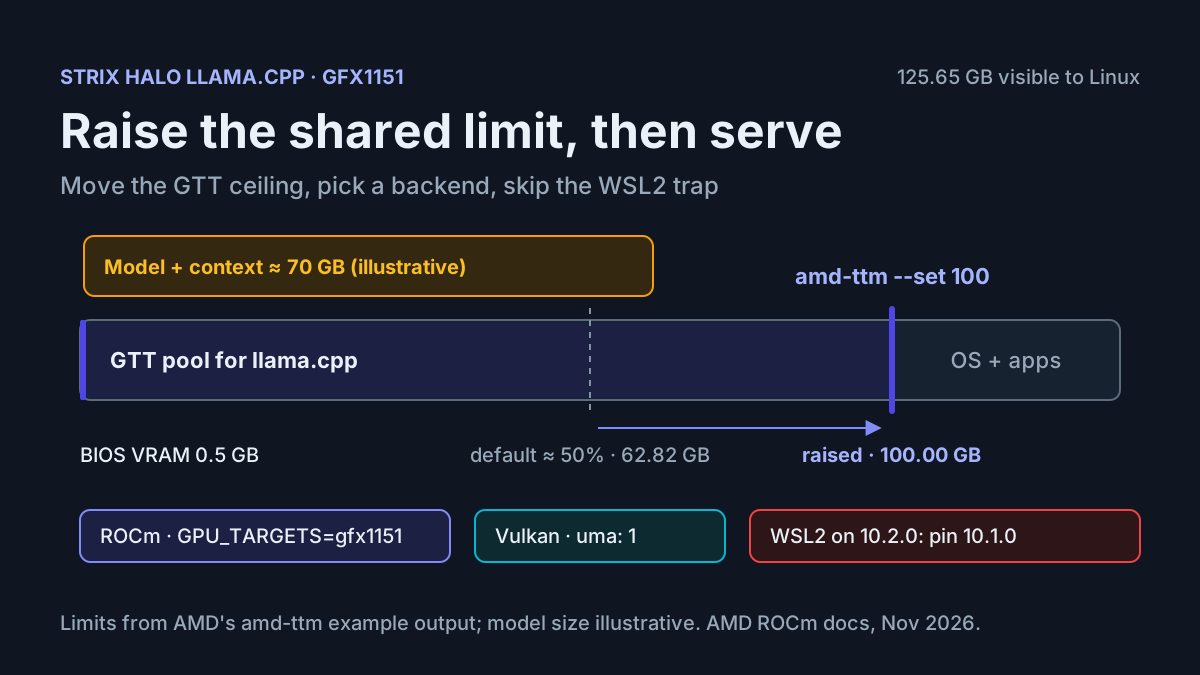
Strix Halo llama.cpp Setup: Raise the GPU Memory Limit, Pick ROCm or Vulkan, Avoid the ROCm 10.2 WSL2 Trap and Serve a Coding Model
Strix Halo llama.cpp setup: raise the shared GTT memory limit with amd-ttm, build for ROCm gfx1151 or Vulkan, dodge the ROCm 10.2 WSL2 bug and serve a model.
Read the story