
llama.cpp Speculative Decoding for Local Coding Models: Draft Models, N-gram Drafting and MTP in llama-server, Measured Before You Trust the Speedup
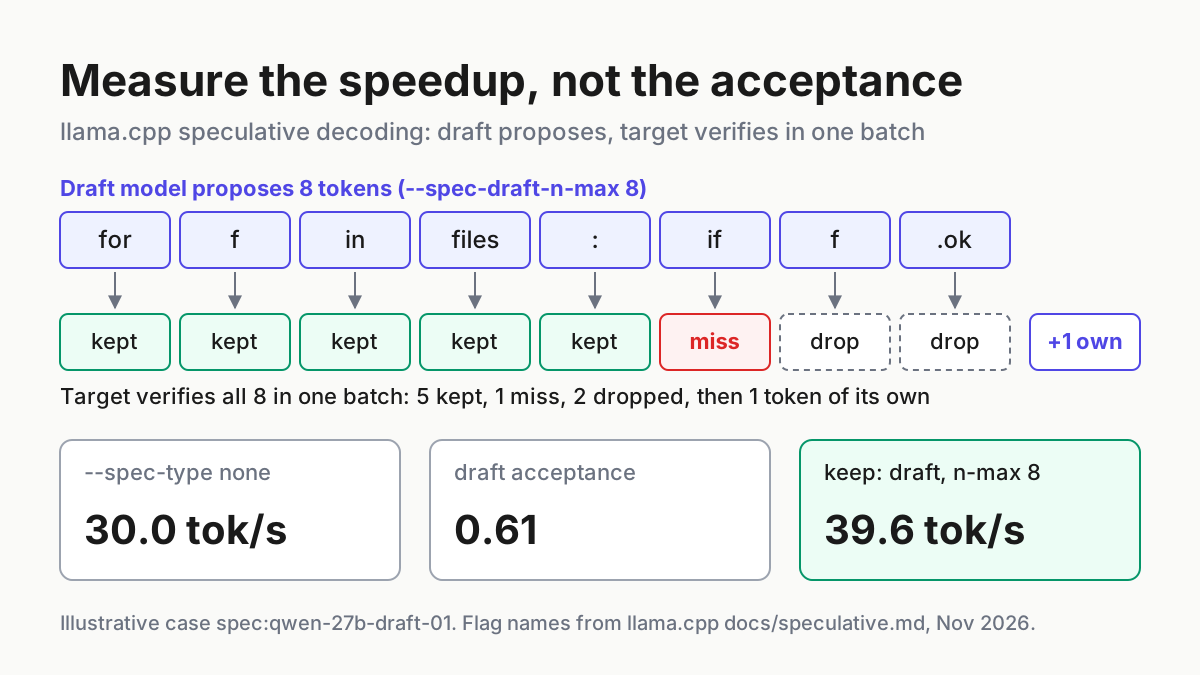
Set up llama.cpp speculative decoding in llama-server with a draft model, n-gram drafting or MTP, then benchmark tokens/s against --spec-type none first.
Read the story