
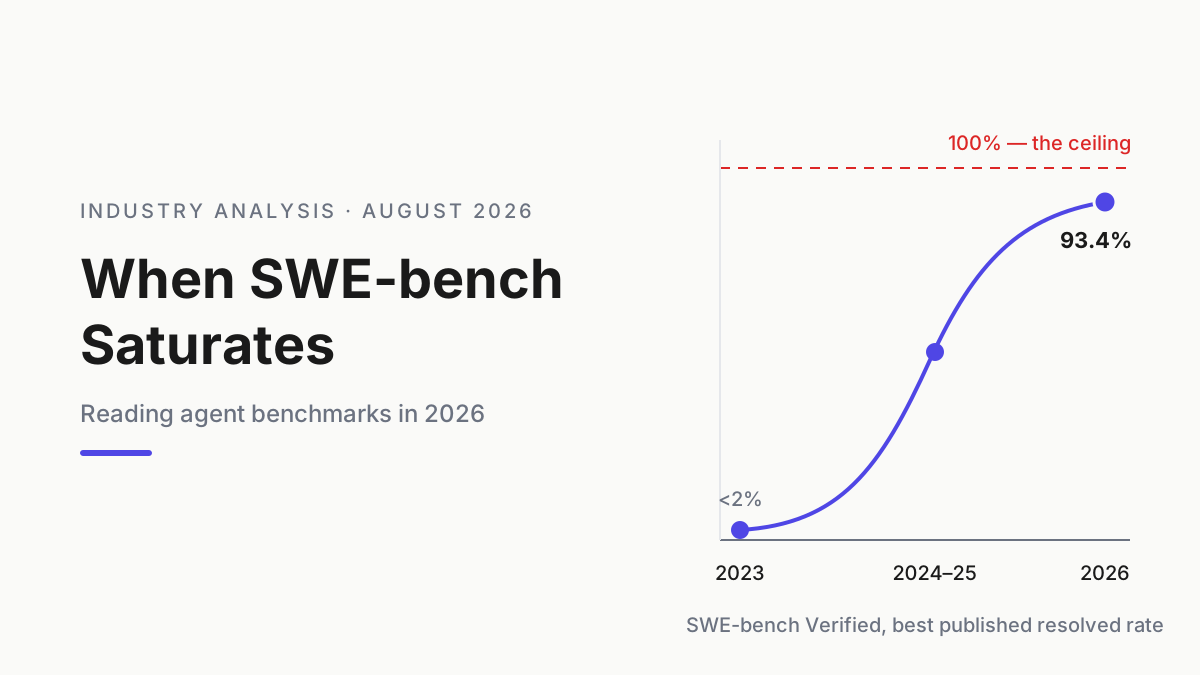
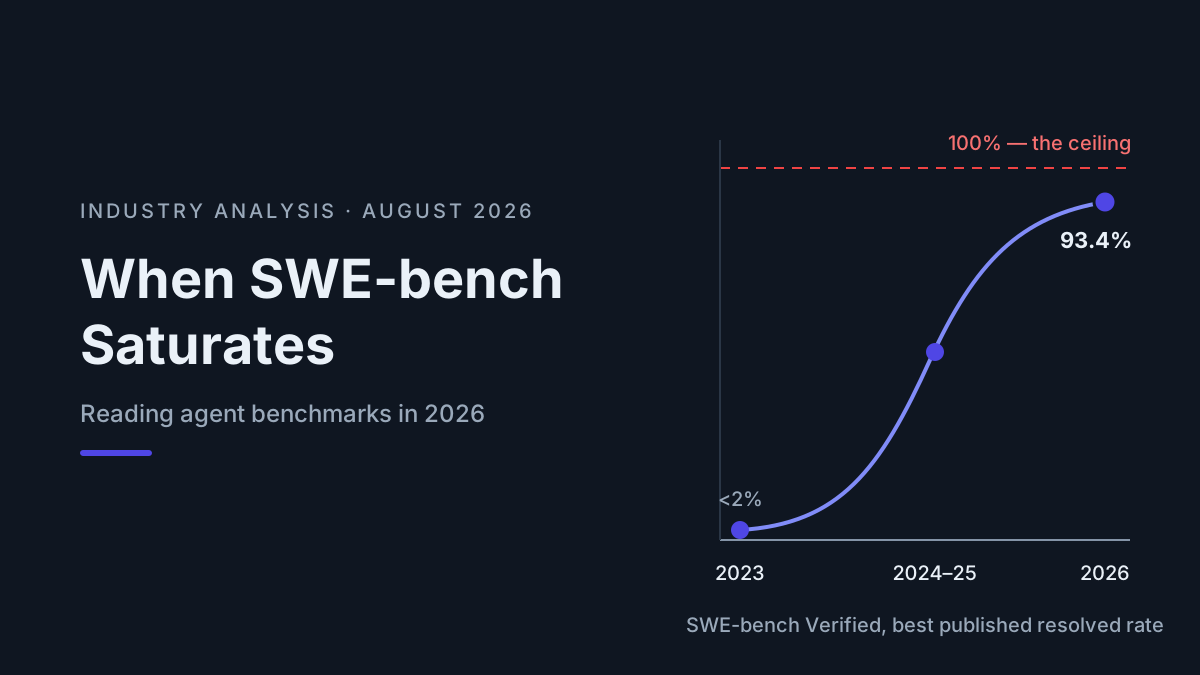
When SWE-bench Saturates: Reading Agent Benchmarks in 2026
SWE-bench Verified is saturating — open models post 78–93%. What scores still predict, how vendors dress them up, and a checklist for reading agent benchmarks.
Read the storyWe use cookies to measure how the site is used and how our ads perform (Google Analytics and Ads, Microsoft Clarity, and the Meta, OpenAI and X ad pixels). “Essentials only” turns off advertising cookies everywhere, and analytics too in the EEA, UK and Switzerland. Privacy Policy
THE INTEL LIBRARY
SWE-bench Verified is saturating — open models post 78–93%. What scores still predict, how vendors dress them up, and a checklist for reading agent benchmarks.
Read the story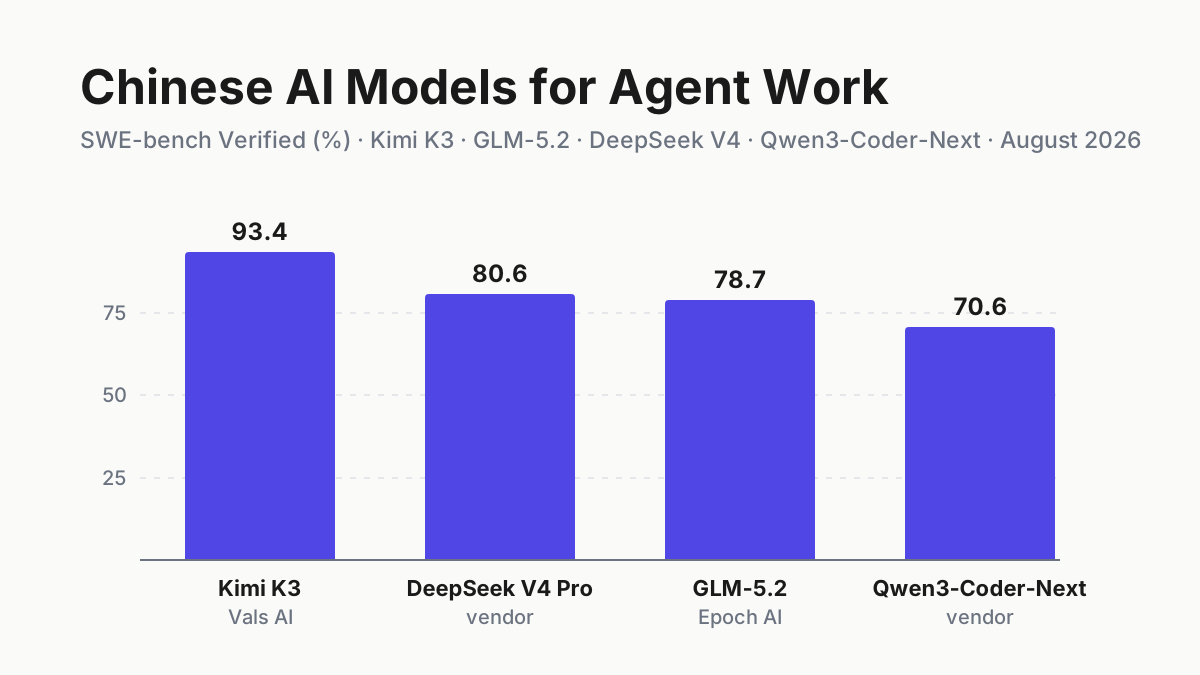
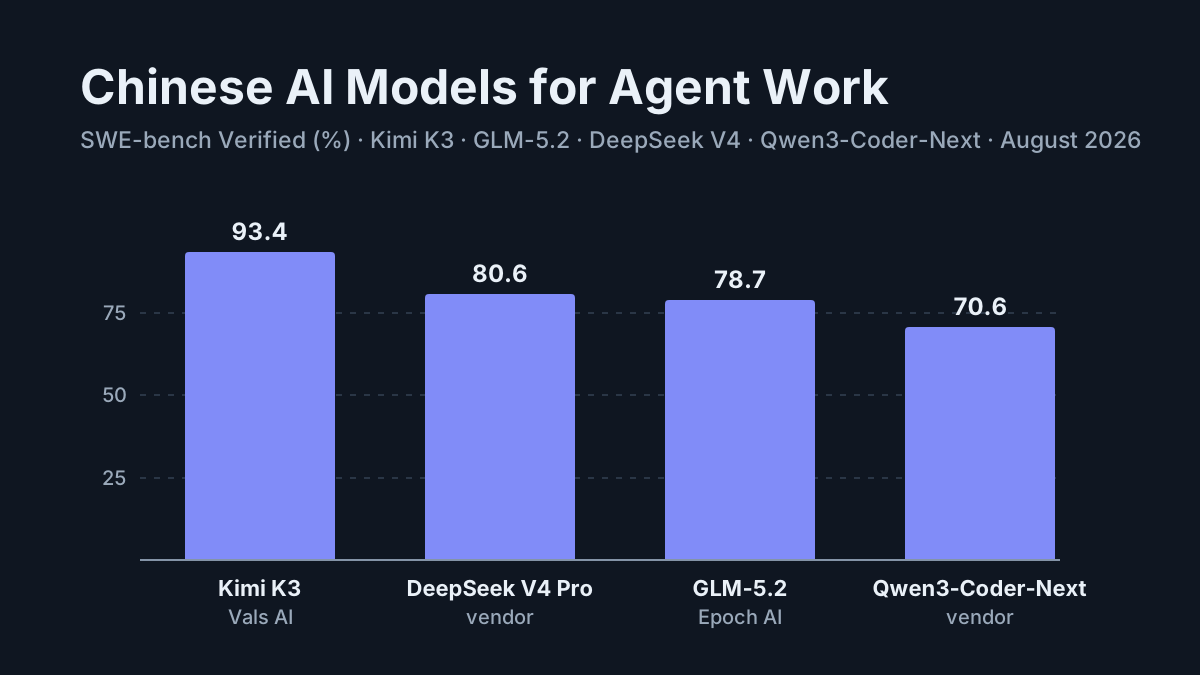
Kimi K3, GLM-5.2, DeepSeek V4, and Qwen3-Coder-Next: a lab-by-lab guide to Chinese AI models for agent work, covering capability, licenses, access, and trust.
Read the storyBring your AI sessions, context, and usage together with Automater.
Get started
Lite is free forever, installs in about a minute, and reads the session history you already have.
Also for macOS (Apple silicon) and Linux.
Signed installer. No account. Session content stays on your disk.
